
U.S.-Based
AI agent evaluation and training data
We test your AI agent on real tasks from your business and show you where it fails. Then we build the training data that fixes it and rerun the same tests, so you can see the score go up.
90+
Active Client Partnerships
80+ Person
Product & Engineering Team
100%
Your Code & IP Ownership
U.S.-Led
Delivery & Accountability
AI training data we create
The next gains in AI won’t come from more of the same data. They’ll come from data that captures how specialists make decisions and how work really gets done. SoftDoes builds that data with vetted experts, scores it with rubrics you can trust, and proves it moved the numbers.
Supervised fine-tuning (SFT)
Expert-written prompt and answer sets with the reasoning shown, so models learn not just the right answer but the path to it.
Reinforcement learning + rubrics
Hard tasks paired with detailed grading criteria written by domain experts, giving your RL pipeline a reward signal grounded in real expertise instead of guesswork.
Agent environments (API / MCP)
Sandboxed, realistic environments where agents call tools, hit APIs, and complete multi-step jobs. Built for both training runs and evaluation.
Computer use trajectories
Real people completing tasks in browsers and desktop apps, captured step by step, so models learn to operate software the way a person does.
Audio & voice data
Accented, multilingual, and noisy real-world speech with multi-speaker diarization and verified transcripts. The data most providers don’t have.
Evaluations & benchmarks
Custom test sets that show exactly where a model or agent breaks, so you fix the right thing before your users find it.



Our work, in short.
AI
Test real tasks. Find and fix failures.
Your team. Your AI.
Teams shipping AI agents. Companies tuning models on their know-how. AI startups needing expert data.
From unclear failure to
measurable gain, in three steps
The capability you want to improve or the agent you need to trust.
Targeted evaluations and benchmarks reveal gaps. Expert-created training data and RL environments address them.
Fine-tuning and re-evaluation until the numbers move.
We don’t just hand you data. We help you use it.
Our team runs supervised and reinforcement fine-tuning on your model or an open-weight base, using the data and evals we built together, so improvements ship in weeks instead of quarters.
Your AI agent looks great in the demo. Does it work in production?
Task success and the measures that matter for your agent, scored the same way before and after.
OutputBefore / after
Which kinds of tasks the agent handles well and which it gets wrong, so you know what is safe to launch.
OutputTask-level results
The exact step where each run went wrong, with the conversation or the tool calls.
OutputFailed runs with context
Failures are ranked by how often they happen, each with the fix we recommend.
OutputPrioritized fixes
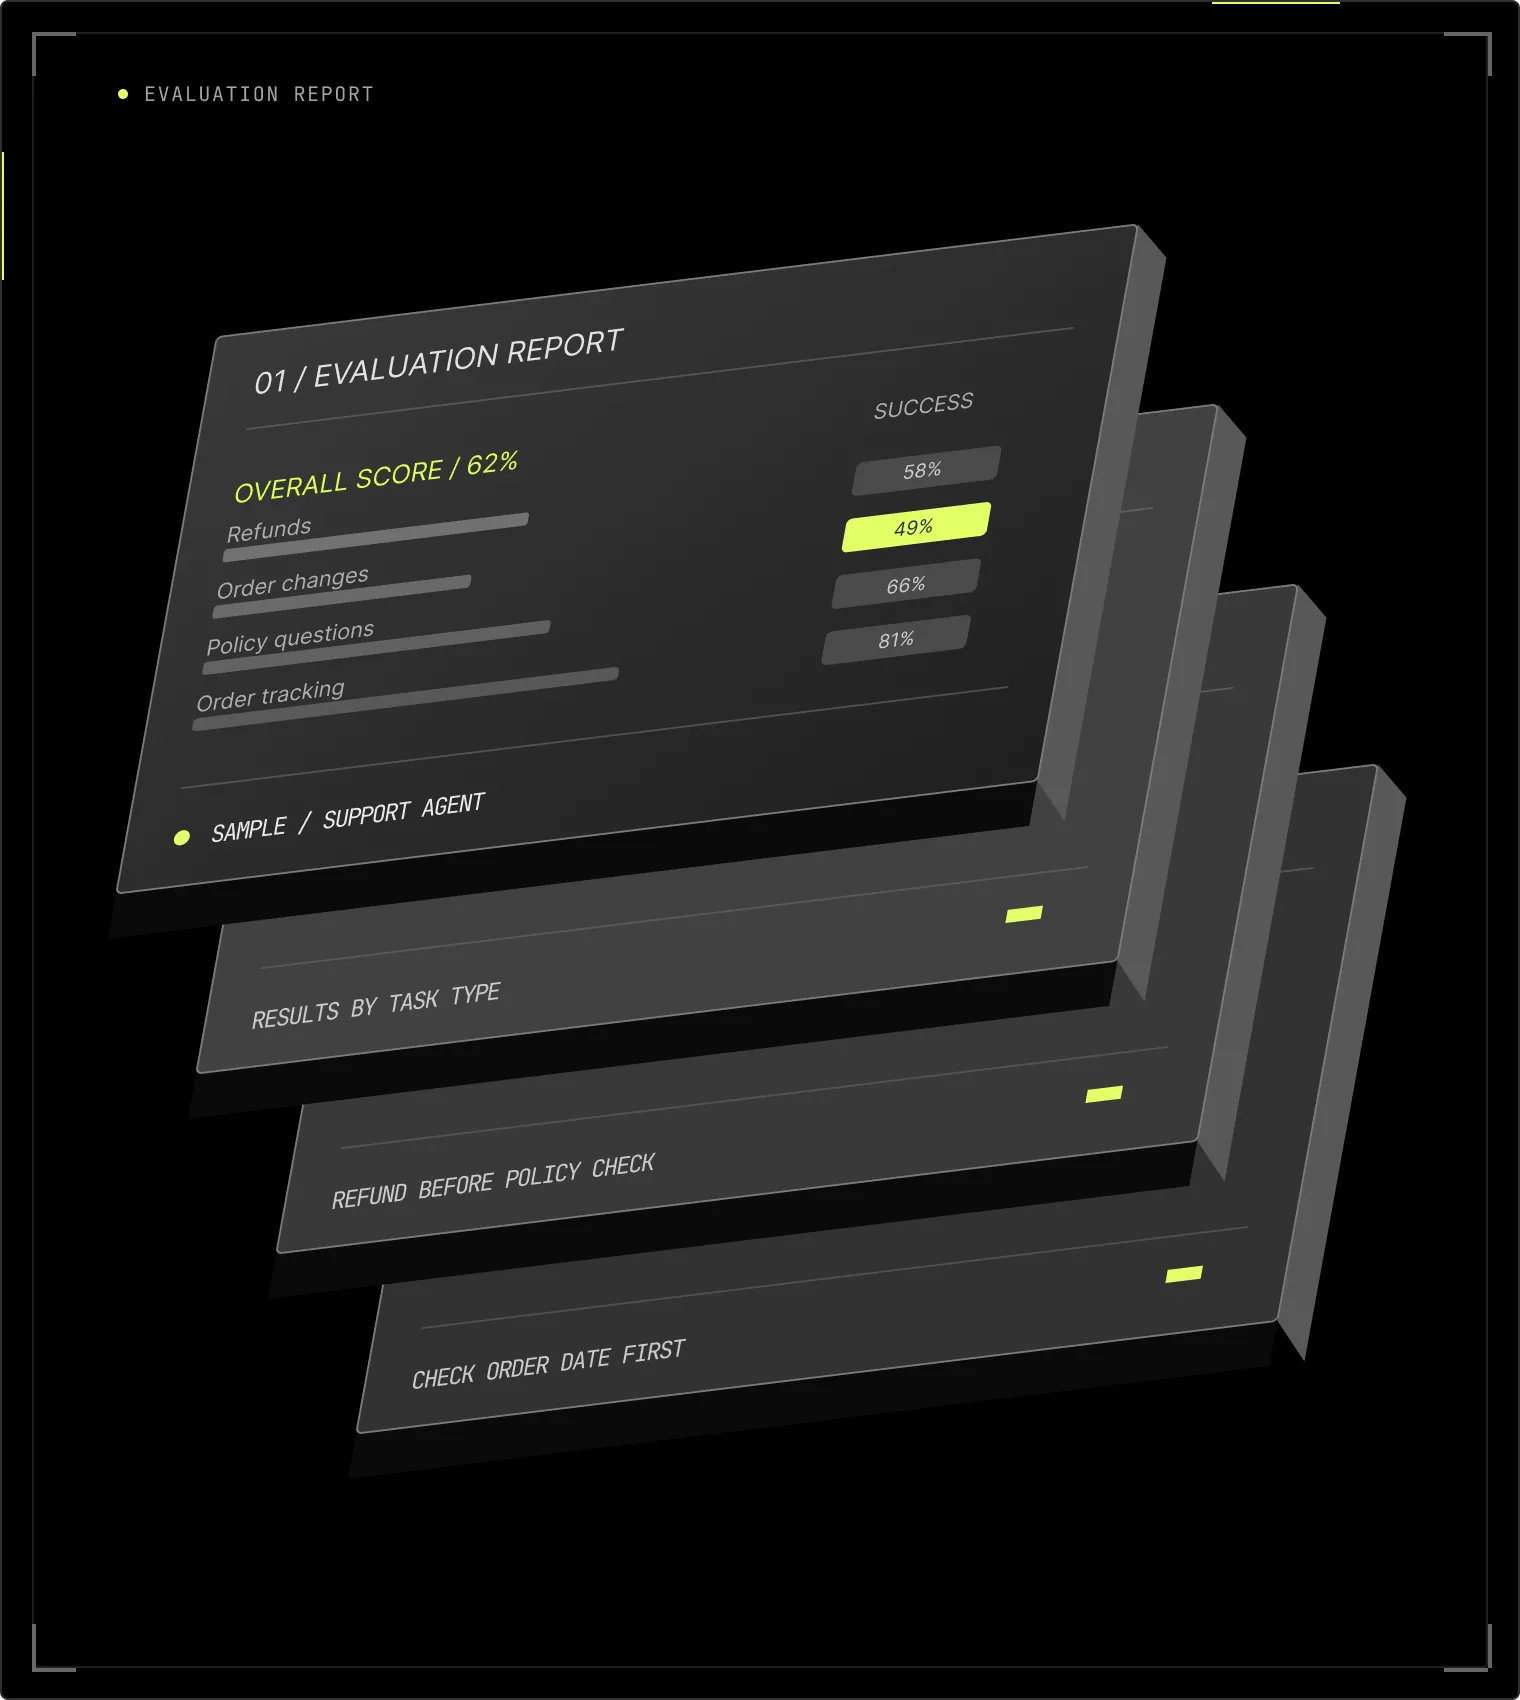
Evaluation, training data and fine-tuning
Start with an evaluation. We add training data and fine-tuning only where the report shows they will help, then measure the gain on the same tests.
1. Evaluate
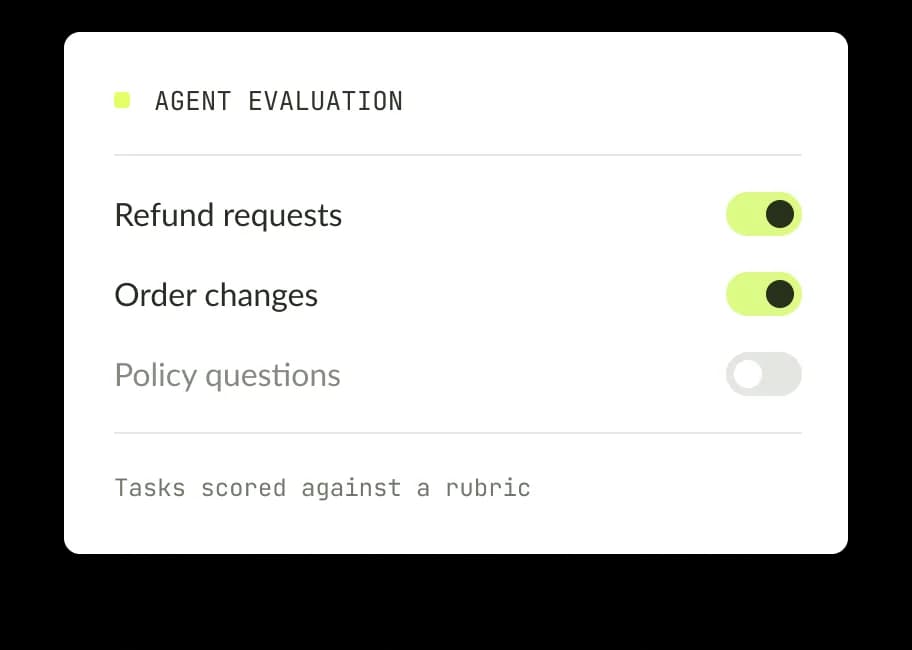
We test your agent on real business tasks. You get a benchmark and a failure report, ranked by how often each error happens.
2. Improve
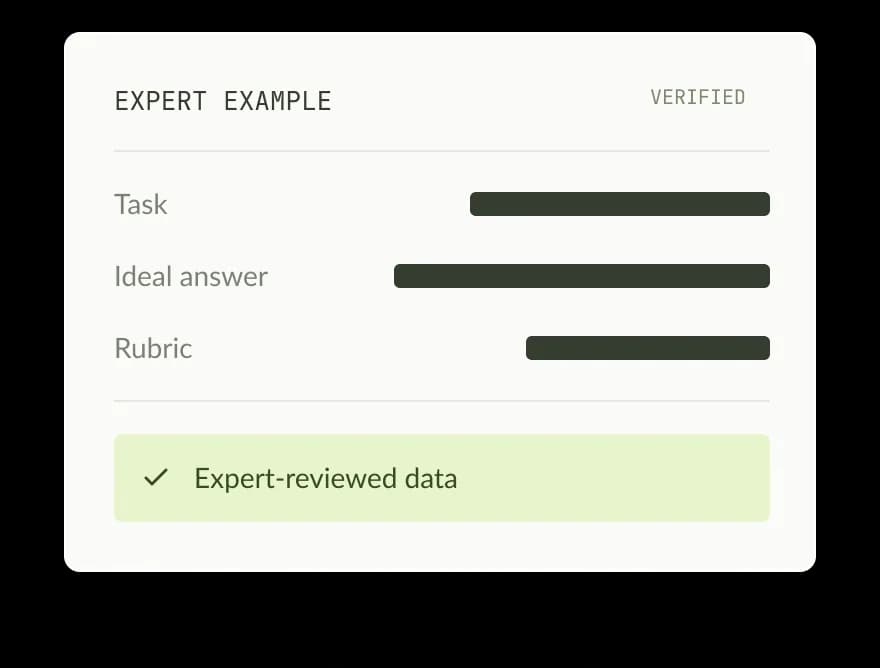
Experts build examples, rubrics and practice environments for the failures we find. You get data in the format your team trains on.
3. Fine-tune
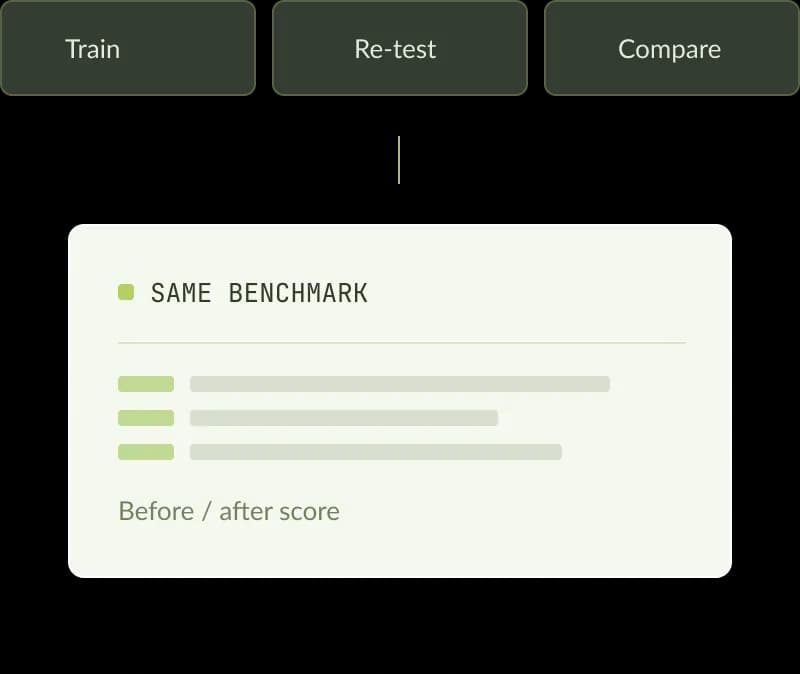
We fine-tune your model or an open-weight model, then repeat the benchmark. You get the model and a before-and-after report.
We’re here to help build AI that’s worth trusting
We believe the best future with AI is one where its benefits reach everyone: an age of abundance where powerful, dependable AI helps people do more, in more fields, than ever before. That future doesn’t arrive on hype. It’s built on unglamorous work: better data, honest evaluation, and models that actually do what they promise. That’s the work we do at SoftDoes. Our team has been building AI safety solutions since before ChatGPT and was among the first to discover prompt injection attacks and report them to OpenAI. Since then we’ve worked with frontier AI labs and some of the largest data providers in the industry, so we know what strong training data and honest evaluations look like from the inside.

Let’s make your AI better
Tell us what you’re building and where it’s falling short.
Questions about AI agent evaluation
How we test your agent, who builds the training data, how your data is protected and what it costs. Can’t find an answer?
What is an AI agent evaluation?
An AI agent evaluation, also called AI agent testing or an eval, is a structured test of how well an agent does its job. We run the agent on realistic tasks and score every run against a rubric, then rank the failures by how often they happen.
What kinds of agents do you evaluate?
We evaluate customer support, sales and research, document, coding and voice agents, whether they run on OpenAI, Anthropic, Google or open-weight models.
Do you also evaluate LLMs on their own?
Yes, LLM evaluation works the same way. We build a test set for your use case and score each answer against a rubric, which also lets you compare models or versions side by side.
Do you need access to our model?
For an evaluation we only need to reach your agent, through its API or a test build. For fine-tuning we need the model itself or access to its fine-tuning API.
Who writes the training data?
Specialists in your field write it, for example nurses, paralegals, accountants or senior engineers. Each one passes a paid test task first, and a second specialist checks every item.
How is our data protected?
We sign an NDA before you share anything. Your data stays in your cloud or in a separate workspace only the project team can open, and we delete it when the project ends.
How long does an evaluation take?
A focused evaluation usually takes about two weeks, from the approved test plan to the report.
How much does it cost?
An agent evaluation starts at $3,500. Training data and fine-tuning are quoted after the evaluation. To build an agent, see AI agent development cost.
Do we own the data and the results?
Yes, you own 100% of the code, data, test sets and reports we create for you, from day one.