We build with Apache Hadoop
We use Apache Hadoop to process and store massive datasets across distributed clusters that support your business goals. From HDFS architecture and MapReduce jobs to integration with your analytics stack, we create products designed to evolve with your needs.
DISCUSS YOUR PROJECTFault-Tolerant Storage
We replicate data across clusters for fault tolerance.
Batch Processing at Scale
We split large jobs into parallel map and reduce tasks.
Ecosystem Compatibility
We connect Hadoop with Hive, HBase, and Spark for analytics.
BENEFITS OF APACHE HADOOP technology
We use Apache Hadoop to store massive datasets reliably, process data in parallel, and modernize legacy big-data infrastructure.
BUILD
[01]- Design HDFS clusters
- Configure YARN scheduling
- Plan data partitioning
- Set replication policies
ENGAGE
[02]- Run MapReduce jobs
- Process batch workloads
- Query with Hive and Spark
- Store semi-structured data
GROW
[03]- Scale cluster capacity
- Add ecosystem tools
- Optimize job performance
- Modernize legacy pipelines
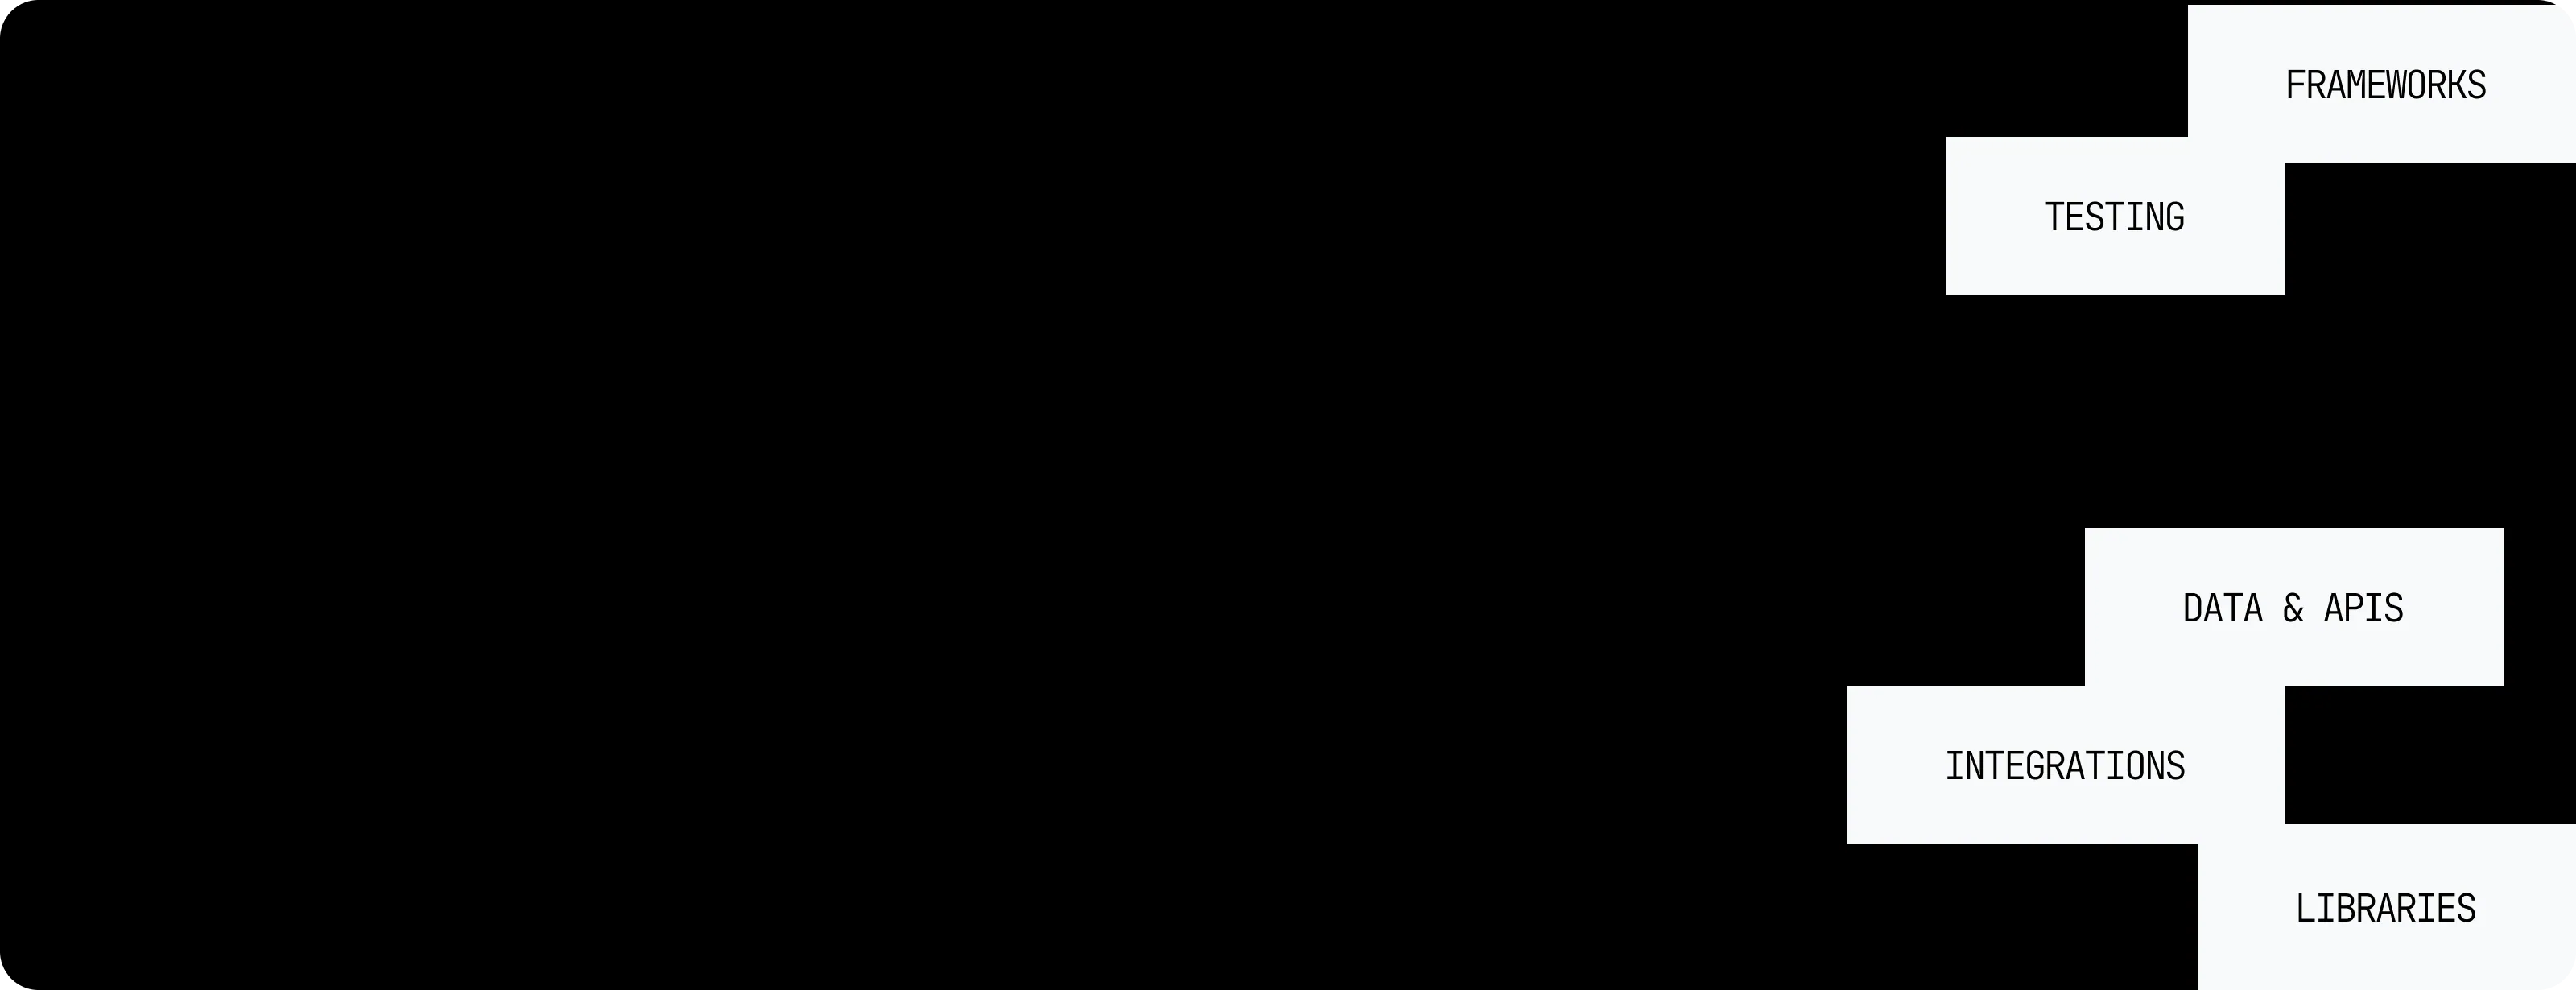
Our Apache Hadoop Technology Stack
We combine Apache Hadoop with Hive, HBase, Spark, and YARN for SQL querying, NoSQL storage, in-memory processing, and cluster resource management across your data infrastructure.
Custom Apache Hadoop development company
With our Apache Hadoop development services, we build distributed storage and batch processing systems for large-scale data warehousing, log analysis, and archival storage, tailored to your boldest business goals. Having years of experience with Hadoop, our engineers harness its full potential to deliver reliable, fault-tolerant infrastructure across industries and company sizes. Whether it's building a new cluster from scratch or modernizing a legacy Hadoop deployment, we design HDFS storage layers and MapReduce or Spark processing pipelines that scale with your data. Our range of Apache Hadoop development services spans consulting, cluster architecture, development, and ongoing maintenance. We work as your technical partner and ensure complete transparency and comfortable communication throughout the process, bringing deep distributed-systems expertise and a pragmatic approach to data infrastructure and problem-solving. All this to make sure your data platform stays reliable and performant as volumes grow, and moves your business forward.
OUR APACHE HADOOP SERVICES
We build, modernize, and support Apache Hadoop data pipelines around your product goals.
Your roadmap is growing faster than your team. Add senior engineering capacity and deliver more without sacrificing quality.
HDFS storage design and YARN resource planning built around your data volume and access patterns.
MapReduce and Spark pipelines that process large datasets reliably across distributed clusters.
Hive, HBase, and Spark connected to your HDFS and YARN layer for broader analytics.
Migrate legacy Hadoop deployments to modern platforms or optimize an existing cluster for performance and cost.


We Turn Technology Into Results
Partner with a team that blends technical precision, creative design, and business insight. We’ll help you launch, scale, and dominate your digital niche.
Frequently Asked Questions
Common questions about how we use Apache Hadoop and what it can bring to your project. Have a specific requirement?
How does SoftDoes use Apache Hadoop?
We use Apache Hadoop to build distributed storage and batch processing systems for large-scale data warehousing, log analysis, and archival storage. We design cluster architecture around your data volume and access patterns.
What types of systems do you build with Hadoop?
We build large-scale data warehouses, log and clickstream analysis pipelines, archival storage systems, and batch processing workloads for organizations managing massive structured and semi-structured datasets.
Can Hadoop integrate with our existing data infrastructure?
Yes. Hadoop's HDFS and YARN layers work alongside tools like Hive, HBase, and Spark, and can sit next to existing relational databases or data warehouses as part of a broader architecture.
Do you work with Hive, HBase, and Spark alongside Hadoop?
Yes. We regularly pair Hadoop with Hive for SQL-style querying, HBase for NoSQL storage, and Spark for faster in-memory processing on top of HDFS and YARN.
When does Hadoop still make sense for a new project?
Hadoop fits well when you need reliable, fault-tolerant storage and batch processing for very large datasets on commodity hardware. For real-time or smaller-scale workloads, other tools may be a better fit.
Can you modernize an existing Hadoop deployment?
Yes. We can optimize an existing cluster's storage and job configuration, migrate workloads to Spark for better performance, or help plan a move to a cloud-native data platform.
How do you decide whether Hadoop fits a project?
We look at your data volume, access patterns, existing infrastructure, and team experience, then confirm Hadoop is the right fit before starting development.