

U.S.-Based
RL environments for training and testing AI agents
We build sandboxed replicas of real software, with tasks and graders, so your agents practice multi-step work and get a reward signal you can trust.
$20,000
Per environment, 50 tasks and graders included
$200
Each extra task, written and graded
5.0
Clutch rating from 40 reviews
How an RL environment runs
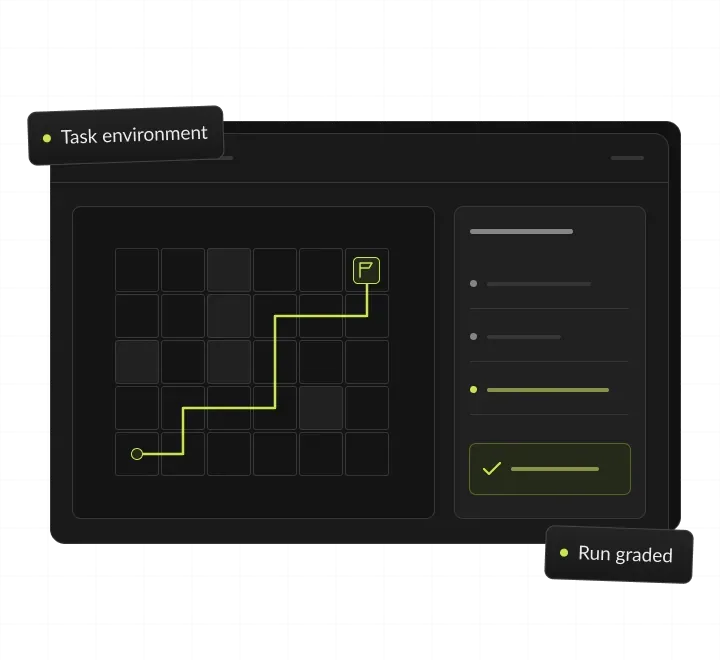
One episode: a task is sampled, the agent acts in the replica, a grader scores the end state and the reward goes to training.
A task is sampled
Refund a damaged order, say.
The agent acts
It calls tools and changes state.
The run is scored
Code checks the end state.
Reward goes to training
Scores and traces to your pipeline.
Reinforcement learning environments, in short
- Kansas City metro software and AI company
- RL environments for AI labs and teams training agents
- Sandboxed replicas of real software, with tasks written by specialists and graders that score every run
- Environments from $20,000 with 50 tasks; extra tasks from $200 each
Replica. Tasks. Graders.
- 01Environment priceFrom $20,000: the app replica, 50 tasks and their graders. Extra tasks from $200 each. Data for the same skill: RLHF and training data
- 02Also for evalsTrain and test: the same environment runs training tasks and held-out evaluation tasks. See AI agent evaluation
- 03Who it's forAI labs and teams training agents on multi-step work
- 04You ownThe code, tasks and graders, in your repository and cloud account
Types of RL environments we build
Five types, what each one is and where it fits. Prices for each environment type are starting points from our price list. Every environment includes the replica, 50 tasks and their graders; hosting runs in your cloud account, billed at cost.
App replica
A working copy of a CRM, help desk, email or spreadsheet app. Fits when your agent must operate business software.
Tool and API sandbox
REST APIs and MCP tools backed by a system that keeps state. Fits when your agent acts through APIs, not screens.
Computer use environment
A browser or desktop app the agent clicks and types in. Fits when the software has no API your agent can call.
Extra task pack
New tasks and graders added to an environment you own. Fits when scores plateau or a new skill is needed.
Held-out evaluation
Tasks that never enter training, scored the same way. Fits when you need a clean measure of progress.
Software we replicate and stacks we plug into
Environments run in containers in your cloud account.
What are RL environments?
An RL environment is a sandbox where an AI agent practices a task and gets a score for each attempt. It holds the software, the tasks and a grader that turns each result into a reward. Reinforcement learning teaches a model by trial and reward. For language model agents, the environment is usually a working copy of business software, so the skills it learns carry over to real jobs.
The parts of an RL environment
State
The data inside the app at any moment, such as the open tickets in a help desk replica.
Actions
The tools and API calls the agent may use, from a search to a refund.
Tasks
Goals written by specialists, each with a known correct end state.
Graders
Code that checks the end state, plus expert rubrics for steps code can't judge.
Reset
A clean restart, so every episode begins from the same seeded data.
Interface
A Gym-style reset, step and reward API that your trainer calls.



RL environment vs benchmark
A benchmark is a fixed test that measures a model at one point in time. An RL environment is interactive: the agent acts, the state changes and the grader scores the result, run after run. The same environment can hold training tasks and a held-out set used only for evaluation. That makes it a training tool and a measuring tool at once.
RL vs supervised fine-tuning
Supervised fine-tuning copies examples of good answers. Reinforcement learning rewards results, so it suits multi-step work where several paths can reach the right end state. Many teams use both: expert training data to teach the format first, then RL on graded tasks to sharpen the skill.
RL environment development: what we build
Realistic software, hard tasks and graders that hold up under training pressure.
App replicas
Working copies of CRMs, help desks, email, spreadsheets or internal tools, seeded with realistic data. For example, a help desk replica seeded with realistic tickets, where the agent must refund a damaged order under the store policy.
Tool and API environments
Agents call APIs and MCP tools against a sandbox that keeps state and returns real responses. For example, an order system exposed as MCP tools, where the agent checks stock, edits an order and confirms the change.
Computer use environments
Browser and desktop tasks, with human trajectories captured step by step for comparison. For example, a browser task to file an expense report, scored against a recorded human run of the same task.
Tasks from specialists
Hard, multi-step tasks written by people who do the job, each with a known correct end state. For example, an accountant writes a month-end reconciliation task and records the exact balances a correct run must produce.
Graders and rubrics
Code checks the final state, and expert rubrics score the steps code can't judge. For example, code confirms the refund posted once, and a rubric scores whether the reply to the customer followed policy. See rubric data.
RL gym for LLM agents
A Gym-style reset, step and reward interface, so your trainer plugs in without glue code. For example, a training loop resets the help desk, sends the agent's tool calls through step and logs each reward to your pipeline.
Risks in RL environments, and how we handle them
Each risk gets a control built into the environment before handover, not a promise in a slide.
When an RL environment pays off
An RL environment pays off when your agent must finish multi-step work in real software. It works best when success can be checked from the end state.
These are the signs we see before a team asks for an environment:
- Your agent passes single-step tests but fails jobs that need many tool calls in a row.
- Static examples stopped moving your scores, and training needs a reward signal.
- Your agents must operate a specific product, such as a CRM, help desk or spreadsheet.
- Success shows in the app itself, such as a record updated or a refund posted.
- You need the same tasks for training runs and for a held-out evaluation.
When to wait
If your agent fails because it lacks examples of good answers, start with expert training data from $5,000. If you don't yet know where it fails, start with an agent evaluation from $3,500.
What to prepare before the first call
The software and the skill you want the agent to learn; how your trainer will call the environment, and where it will run; a few examples of hard tasks, or the people who can describe them; and how you will judge success: end-state checks, rubric scores or both.
What you get with every RL environment
You get a working environment you can run without us: the replica, the tasks, the graders and the documents, in your repository and your cloud account.
RL environment ROI: a worked example
An RL environment pays back through reuse: one build serves many training runs and every evaluation after them. This example uses assumed task counts and training runs, not a client result, so swap in your own. Each added run lowers the cost per graded attempt, because the replica, tasks and graders already exist; hosting and compute are billed at cost in your cloud account, on top of this math. The return shows up on the held-out tasks: the same graders score the agent before and after each run, on tasks it never trained on. Compare this cost with the engineer time an in-house build would take, including grader testing and task writing by specialists.
How we build an RL environment
From the skill you want to a tested environment in your cloud.
We agree the software, the skill your agent lacks and how success is judged. You see the spec, the task list and a fixed price before any build. You get a spec and a task list.
We build the sandboxed app with seeded data, tools and a clean reset. It runs in containers, so every episode starts from the same state. You get a working replica.
Specialists write 50 tasks; engineers test each grader on known answers. A second specialist checks every task before it ships. You get 50 tasks with tested graders.
We run baseline agents, document the interface and add tasks on request. Held-out tasks stay out of training, so evaluation scores stay honest. You get baseline scores and docs.
The team behind your environments
Our team has worked with frontier AI labs and some of the largest data providers in the industry.

- Healthcare
Prior Authorization AI
Prior Authorization AI is a healthcare automation startup building AI-powered tools to streamline prior authorization for Medicare and Medicaid medical transportation providers in New Jersey.- 16Weekly hours saved
- 63%Admin time reduced
- 43%Fewer submission errors

- Startup
- Real Estate
Our Haus AI
A finance professional turned founder built Our Haus AI, an AI-powered collaborative workspace where homeowners and contractors scope, bid, contract, and document renovation projects together. SoftDoes took her prototype and made it production-ready.- 10XMVP scope delivered
- 2+years Ongoing partnership
- 1Fully owned Platform

- Real Estate
The building buyer
The Building Buyer is a Florida-based real estate investment firm co-founded by Dylan Troiano and Charles Hanlin. They acquire single-family, multifamily, and commercial properties across South Florida and beyond, with a focus on motivated seller opportunities.- 18Weekly hours saved
- 2+Years Ongoing partnership
- 1Fully owned Platform

- Healthcare
CareInTouch
CareInTouch is a Bay Area home health agency providing skilled nursing and therapy services to patients referred from hospitals and clinics. With over 100 staff, they operate in one of the most complex and compliance-driven healthcare markets in the country.- 40% Reduction In Billing Errors
- 100+Staff Operations Managed
- 0Missed Compliance Deadlines

- Startup
Sparkle The Cleaning Service
Sparkle The Cleaning Service is a Detroit-area residential cleaning company with 10 years in business, connecting homeowners with vetted, insured independent cleaners through a subscription-based marketplace platform.- 75% Platform Transparency
- 2XPlatform Growth
- 40%Higher User Retention

- Healthcare
FMY Orthodontics
FMY Orthodontics, a multi-location practice in West Tennessee, partnered with SoftDoes to replace a spreadsheet-based financial workflow with a custom web platform. The goal was to simplify how staff present treatment financing while allowing patients and families to review and complete decisions remotely.- 60%Workflow Reduction
- 75%Remote Adoption
- 5Locations Aligned

- Real Estate
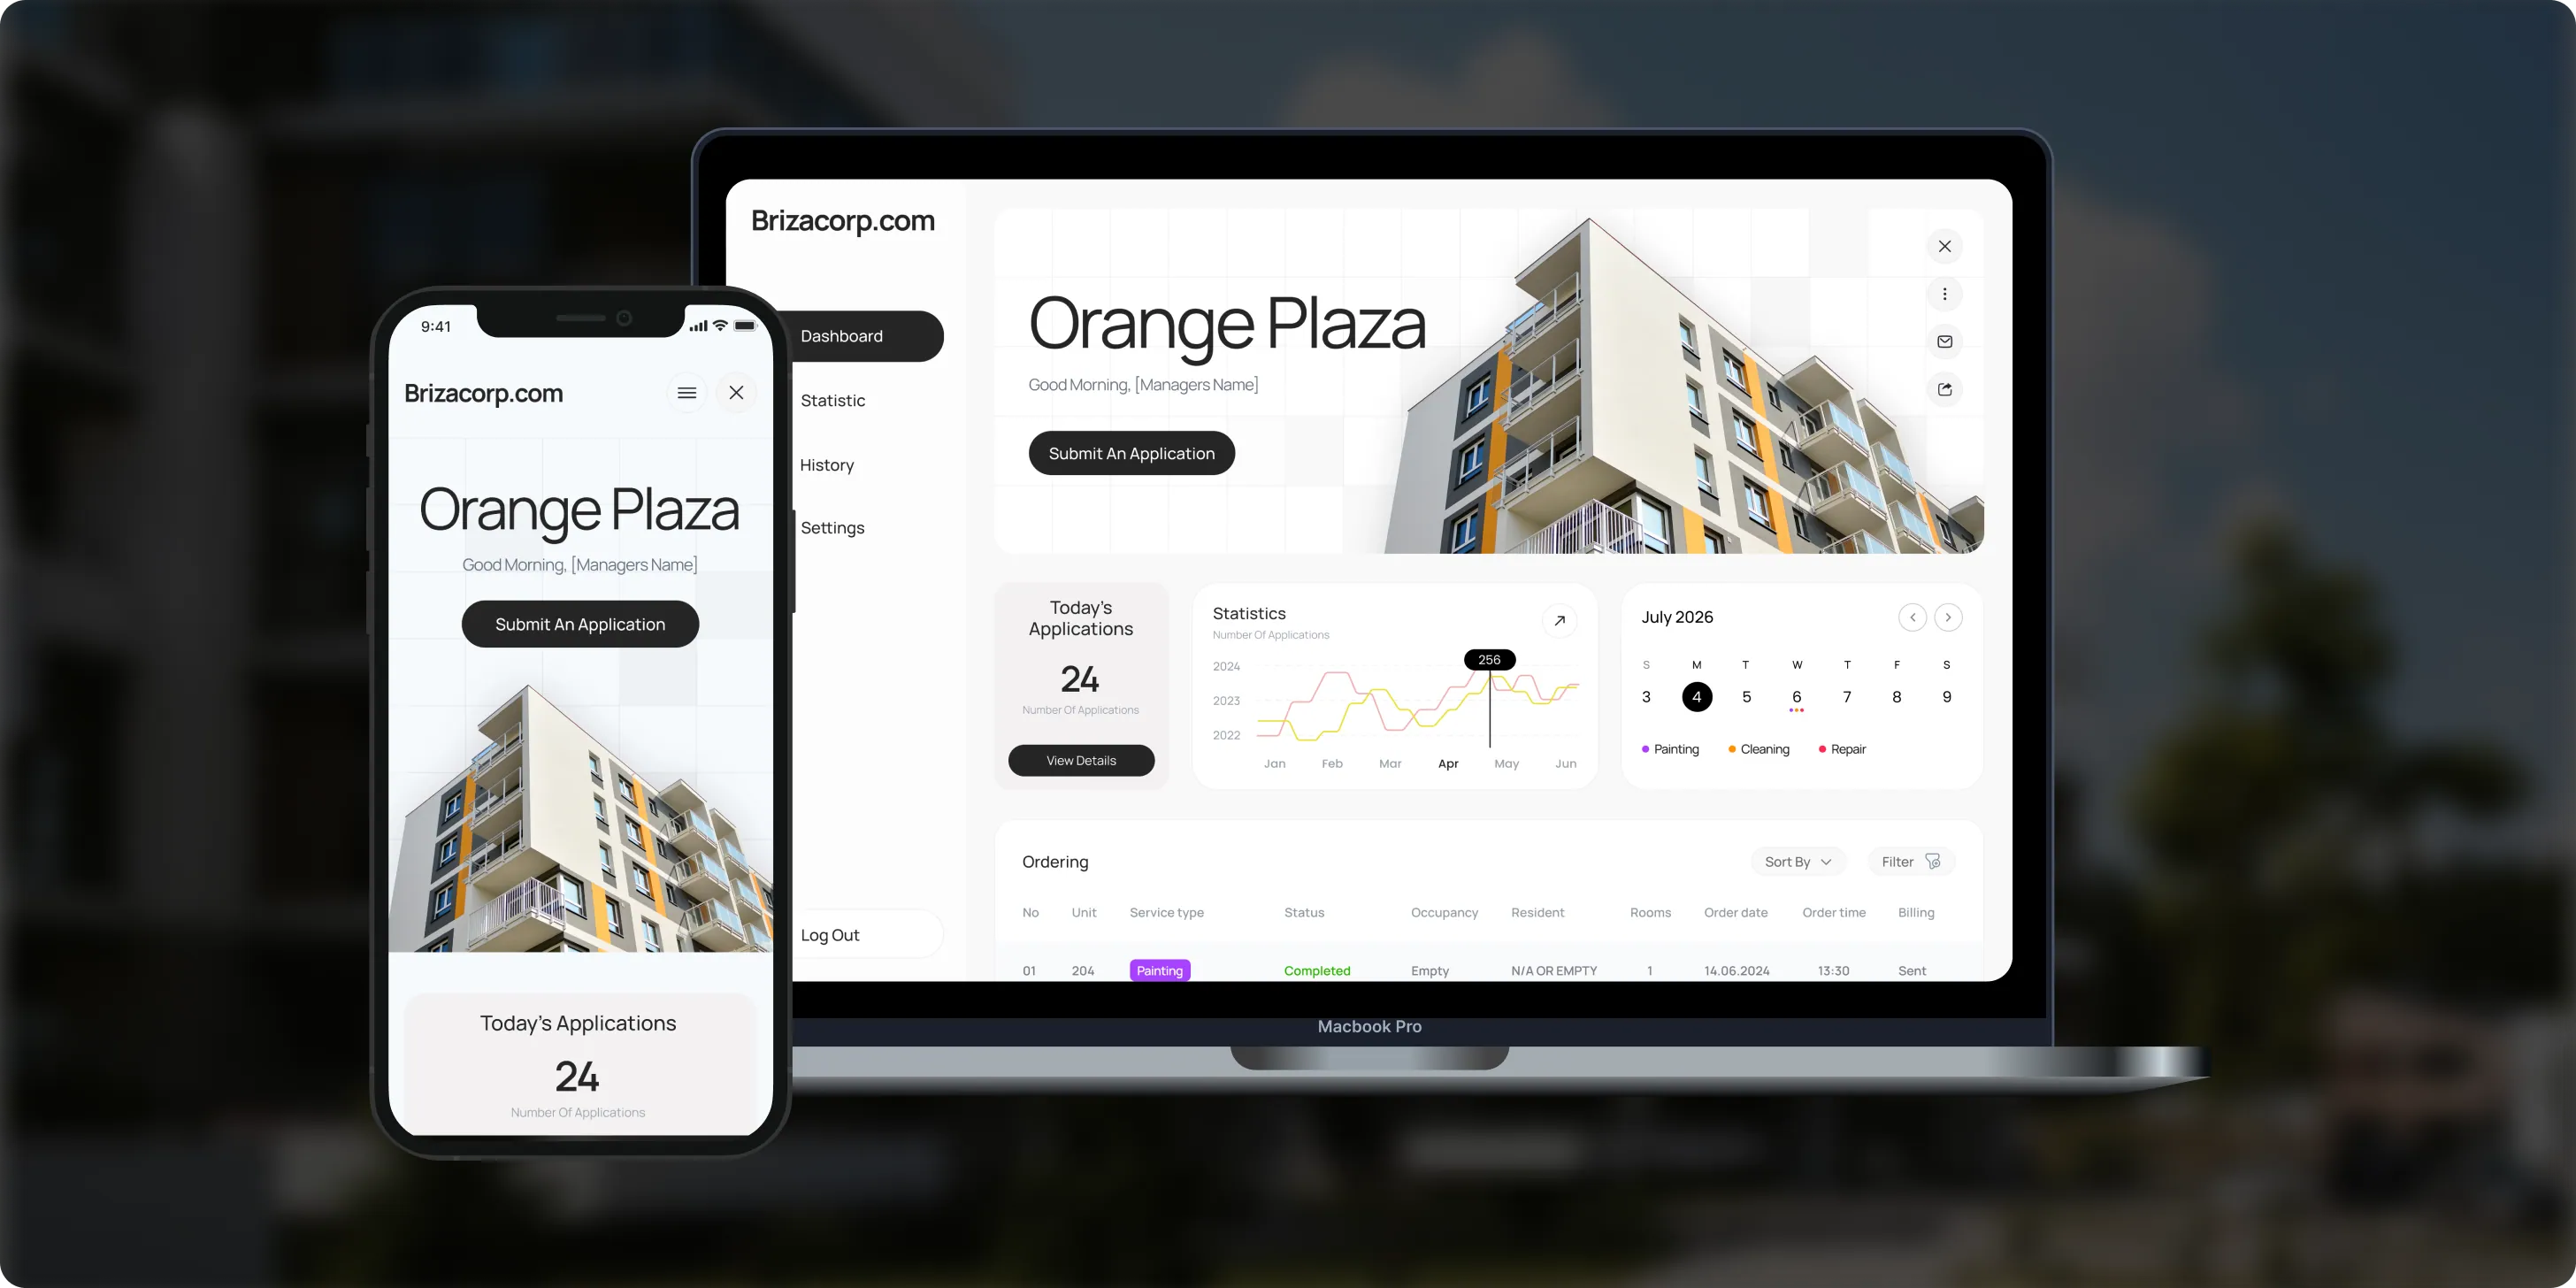
Brizacorp
Brizacorp manages residential properties and coordinates the staff who handle painting, cleaning, and repair requests. Its team tracked work across messengers, phone calls, e-mail, and paper planners, with no single place to manage requests or measure performance.- 98%Application Stability
- 95%Utilization Rate
- 30%Faster Task Completion
Why AI labs work with SoftDoes
AI labs work with SoftDoes for frontier lab experience, vetted specialists and full ownership of every environment we build.
- 01
Frontier lab experience
Our team has worked with frontier AI labs and some of the largest data providers in the industry.
- 02
You own the environment
You own all the code, tasks, graders and test sets we build, under our NDA signed before work starts.
- 03
Vetted task writers
Each specialist passes a paid test task, and a second specialist checks every task.
- 04
Claude and OpenAI partner
A Claude Partner Network member and an OpenAI Registered Partner, building on both platforms.
- 05
40 AI projects since 2020
About 80% of our projects include AI, and 40 AI projects have been delivered since 2020.
- 06
Rated 5.0 on Clutch
5.0 from 40 client reviews. Clutch named SoftDoes a Top Artificial Intelligence Company and Top Machine Learning Company in Kansas City for 2026.
How we keep your environment and data private
Your environment, tasks and data stay under your control. We sign an NDA before you share anything, and everything runs in your own cloud account.
Insured, and vetted
Our certificate of insurance reaches your procurement team before the first call. For rules on AI use inside your company, see AI governance and compliance.
NDA first
The NDA is signed before any spec, data or model detail is shared.
Your cloud account
Environments run in containers in your cloud account, billed at cost.
A separate workspace
Project data stays in your cloud or in a separate workspace that only the project team can open.
Deleted at the end
We delete project data when the project ends.
You own everything
You own 100% of the code, tasks, graders, test sets and reports from day one.
Vetted task writers
Task writers pass a paid test task before they start on your project.
RL environment pricing
A fixed price per environment, set by app size, task difficulty and grading depth. Hosting runs in your cloud account, billed at cost.
RL environment
App replica, 50 tasks, graders
From $20,000
Extra tasks
Written and graded
From $200 each
Expert training data
For the same skill
From $5,000
Agent evaluation
On held-out tasks
From $3,500
Project Discovery
Credited to the build
$490
How to choose an RL environment company
Ask these questions before you sign. A strong RL environment vendor answers each one in writing.
Questions to ask, and what a good answer includes
- Who writes the tasks? People who do the job, vetted with a paid test task, with a second check on every task.
- How are graders tested? Runs against known right and wrong answers before any training.
- How do you catch reward hacking? End-state checks, plus a search of baseline runs for high scores without the work.
- Is there a held-out set? Tasks that never enter training, scored the same way as training tasks.
- Will it plug into our trainer? A documented reset, step and reward interface, with no adapter code.
- Where does it run, and who owns it? Your cloud account, with all code, tasks and graders owned by you.
- What paperwork comes first? An NDA and a certificate of insurance before the first call.
RL environments by industry
Specialists from each field write the tasks, inside replicas of the software that field runs on. Each industry page shows that field's AI use cases and rules in detail.
Healthcare
Tasks written by clinical specialists such as nurses, in replicas of scheduling and records software.
Legal
Paralegals write intake, deadline and document tasks inside a case management replica.
Financial services
Account servicing and document review tasks in back-office replicas, with every step logged.
Accounting
Accountants write reconciliation and close tasks in spreadsheet and ledger replicas.
Insurance
Claims intake and review tasks, graded on the record the agent leaves behind.
Logistics
Dispatch and shipment exception tasks in carrier and warehouse system replicas.


Questions about RL environments
What they are, how we build them and what they cost. Can't find your answer?
What is an RL environment?
An RL environment is a sandbox where an AI agent practices a task and gets a score. It holds the software the agent works in, a set of tasks and a grader that checks each attempt. Training rewards the attempts that score well. For language model agents, the software is often a replica of a real business app.
What does RL mean in an AI context?
RL means reinforcement learning: a model learns by trying actions and getting a reward or a penalty for the result. For language models and agents, RL comes after pretraining and fine-tuning. It teaches multi-step skills, such as finishing a support case in a help desk, that examples alone teach poorly.
How do you make an RL environment?
We pick the software and the skill, then build a sandboxed replica with seeded data, the tools the agent may call and a clean reset. Specialists write tasks with a known correct end state. Engineers write graders, test them against known answers and run baseline agents before handover.
How much does an RL environment cost?
An environment starts at $20,000 and includes the app replica, 50 tasks and their graders. Extra tasks start at $200 each. The price depends on the size of the app, how hard the tasks are and how much the graders must check. Hosting runs in your cloud account at cost.
How do you stop agents from gaming the grader?
Graders check the final state of the app, not the agent's own report of success. Where code can't judge the steps, an expert rubric scores them. Before handover we run baseline agents and look for runs that score well without doing the task, then close those gaps in the grader.
Can the same environment be used for evaluation?
Yes. Every environment we build runs both training runs and evaluation. We keep a set of held-out tasks that never enter training, so your scores show real progress. Our AI agent evaluation service uses the same approach for agents already in production.
Who owns the environment and the tasks?
You do. You own 100% of the code, the replica, the tasks, the graders and the reports from day one. We sign an NDA before you share anything. The environment runs in your own cloud account, so you can extend it with your own team or with us.
What are some examples of reinforcement learning?
In AI products, reinforcement learning trains models on tasks with a clear result. One example is an agent closing a support case in a help desk replica. Others are a browser agent filing an expense report and a model solving problems whose answers can be checked. In each case a grader scores the outcome, and training rewards the attempts that succeed.
Do we need a custom RL environment, or can we use an open-source one?
Open environments are a good start for research and common skills. A custom environment pays off when your agent must operate a specific product, follow your policies or learn tasks no public set covers. Many teams use both: public environments for general skills and a custom replica for the work that matters to their product.
How long does it take to build an RL environment?
It depends on the size of the app, the number of tasks and how much the graders must check. We agree the scope, the task list, the schedule and a fixed price in a written spec before the build starts. Any project can begin with Project Discovery for $490, which is credited to the build.
How many tasks does an RL environment need?
Every environment we build starts with 50 tasks and their graders. Teams add more when scores plateau or a new skill is needed, from $200 per task. Keep part of the set held out for evaluation, so you can see whether training carries over to tasks the agent never saw.
Can you build an environment around our own product?
Yes, as long as we can study how the product behaves, through its documentation, a test build or sessions with your team. We replicate the screens, tools and data your agents will meet, with a clean reset. Your product details stay under the NDA, and the environment runs in your own cloud account.
What is the difference between RLHF and an RL environment?
RLHF trains on human preferences: specialists rank model answers, and a reward model learns those rankings. An RL environment rewards results instead: a grader checks whether the agent finished the task in the software. Many teams use both. We build preference data on our RLHF and training data page.
Which RL frameworks does the environment work with?
Any trainer that can call a Gym-style reset, step and reward interface. The environment runs in Docker or Kubernetes in your cloud account, so your own RL trainer drives it directly. We document the interface and run baseline agents before handover, so your team starts from known scores.
Updated · Reviewed by Orest Andrusyshyn, Founder and CEO


