Machine Learning Model Development in San Francisco, CA
Machine Learning Model Development in San Francisco, CA
SoftDoes provides machine learning model development for San Francisco companies that need production ML models. From custom model training to full MLOps monitoring, we turn business data into reliable AI systems that perform beyond the notebook stage.
Let's build together.
Talk with a senior engineer about your product idea, architecture, and what it would take to build it.
90+
Active Client Partnerships
80+ Person
Product & Engineering Team
100%
Your Code & IP Ownership
U.S.-Led
Delivery & Accountability
Services we offer
- 01Machine Learning Model Development
> FROM RAW DATA TO PRODUCTION MODELS <
Production ML projects often fail when models leave the notebook. That gap between a promising experiment and a reliable production system is where most teams lose months and budget. Our ML model development process addresses this directly. We engineer machine learning models using frameworks like TensorFlow and PyTorch, selecting the right machine learning algorithms for each use case, whether that means gradient boosted trees for tabular business data or deep neural networks for image recognition tasks.
- Supervised and unsupervised model training
- Hyperparameter tuning and cross validation
- Model validation on holdout datasets
- Containerized deployment pipelines
- Continuous evaluation and retraining
> KEEPING MODELS ACCURATE OVER TIME <
How do you ensure a machine learning model stays accurate after launch? We integrate MLOps monitoring from the first commit, tracking drift, latency, and prediction quality across every serving endpoint.
- Feature and concept drift detection
- Automated alerting on performance degradation
- Scheduled retraining workflows
- Model versioning and rollback support
- 02Artificial Intelligence Development
> Intelligent Systems That Solve Real Problems <
San Francisco is the global epicenter of machine learning and artificial intelligence innovation, yet many companies still struggle to move from concept to a working AI product. Our team designs and engineers artificial intelligence systems that address concrete operational gaps. We map your data landscape, identify where AI can reduce manual effort or unlock new capabilities, and then architect a solution that fits your existing infrastructure. Every engagement starts with a technical discovery session so we understand the problem before writing a single line of code. The city has one of the highest concentrations of AI startups globally, which means your competitors are already investing. We work with founders and CTOs across the San Francisco, Bay Area, who need AI solutions that go beyond demos. Whether you need natural language processing pipelines, recommendation engines, or classification systems, our engineers handle the full spectrum from data preparation through deployment. The result is an AI product that works on production data, not just on a curated test set.
- Custom model architecture design
- Data pipeline engineering
- Integration with existing platforms
- Bias detection and fairness audits
- Production readiness assessment
- 03AI-Driven Process Automation
> AUTOMATE WHAT SLOWS YOUR TEAM DOWN <
Repetitive manual workflows consume engineering hours that should go toward innovation. Our intelligent automation services use AI and machine learning to identify bottlenecks in your operations and replace them with automated workflows that run reliably at volume. Implementing automated workflows is essential for managing the ML lifecycle and reducing human error. We connect these systems to your existing tools so adoption happens without disruption. Companies across the Bay Area are moving from AI experimentation to scalable production deployments, and process automation is often the fastest path to measurable ROI. We engineer document classification pipelines, automated data extraction, and decision support systems that handle specific tasks your team currently does by hand. Each automation is designed with observability so you can track performance and intervene when needed. The goal is operational efficiency that compounds over time.
- Document processing and classification
- Automated data extraction pipelines
- Workflow orchestration and scheduling
- Exception handling and fallback logic
- Performance dashboards and logging
- 04Custom AI Solutions
> ENGINEERED FOR YOUR EXACT REQUIREMENTS <
Off the shelf AI tools solve generic problems. When your business needs something specific, whether that is a proprietary computer vision pipeline, an AI agent that navigates complex decision trees, or a generative AI system trained on your domain knowledge, you need custom ML model development. We work with your team to define requirements, select the right foundation models or training approaches, and engineer a solution that integrates cleanly with your stack. High quality training data and data consistency are critical in this process, and we help you get both right. The local tech ecosystem in San Francisco supports rapid experimentation and hyperparameter tuning for ML models, and we take full advantage of that speed. From large language models fine tuned on your corpus to reinforcement learning systems that optimize complex sequences, every solution is purpose engineered. We handle everything from data science exploration through production rollout.
- Domain specific model fine tuning
- Multi modal and agentic system design
- RAG pipeline engineering
- Custom evaluation and testing frameworks
- Long term maintenance and iteration
- 05AI Operationalization
> GETTING AI INTO PRODUCTION AND KEEPING IT THERE <
A trained model sitting in a Jupyter notebook generates zero value. Operationalization means packaging, deploying, monitoring, and maintaining ML models so they serve real users under real conditions. We engineer robust MLOps practices that improve reliability and reproducibility across the entire ML lifecycle, including advanced automation with AI and ML. Our team handles containerization, API endpoint design, load testing, and response time SLAs so your system performs under pressure. MLOps monitoring is essential for production machine learning projects. We set up continuous evaluation pipelines, drift detection, and automated alerting before your model ever serves its first request. Local firms in San Francisco utilize platforms like Google Cloud and AWS for model training and deployment, and we work across all major cloud providers without vendor lock in for practical ML implementation within current operations. Compliance architecture gets established from day one, especially critical for companies handling sensitive data and AI-powered workflows. We also support computer vision models when teams need to deploy computer vision models in production at scale.
- CI/CD pipelines for model deployment
- Infrastructure as code for reproducibility
- Real time inference serving and optimization
- Cloud and edge deployment options
- Governance and audit trail setup
> FROM RAW DATA TO PRODUCTION MODELS <
Production ML projects often fail when models leave the notebook. That gap between a promising experiment and a reliable production system is where most teams lose months and budget. Our ML model development process addresses this directly. We engineer machine learning models using frameworks like TensorFlow and PyTorch, selecting the right machine learning algorithms for each use case, whether that means gradient boosted trees for tabular business data or deep neural networks for image recognition tasks.
- Supervised and unsupervised model training
- Hyperparameter tuning and cross validation
- Model validation on holdout datasets
- Containerized deployment pipelines
- Continuous evaluation and retraining
> KEEPING MODELS ACCURATE OVER TIME <
How do you ensure a machine learning model stays accurate after launch? We integrate MLOps monitoring from the first commit, tracking drift, latency, and prediction quality across every serving endpoint.
- Feature and concept drift detection
- Automated alerting on performance degradation
- Scheduled retraining workflows
- Model versioning and rollback support
PRODUCTS BUILT ACROSS INDUSTRIES
Finance
Predictive analytics and anomaly detection models help financial teams flag risk, forecast revenue, and automate compliance checks using machine learning techniques applied to transaction data.
Healthcare
Deep learning networks trained for healthcare applications support diagnostic imaging, patient outcome prediction, and clinical document processing while meeting strict data privacy requirements.
Education
Personalized learning platforms use predictive modeling and data analysis to adapt content delivery, identify struggling students, and improve outcomes across educational institutions.
Construction
ML models for construction optimize scheduling, forecast material needs, and run quality control checks on site imagery, helping teams reduce rework and stay on timeline.
Technology
Software development teams at technology companies apply machine learning to platform optimization, user behavior analysis, and feature prioritization using large datasets and real time telemetry.
Startups
Startups in San Francisco often specialize in reinforcement learning and tailored data solutions. We help them move from prototype to production fast with focused ML app development.
Compliance
Automated regulatory monitoring and document classification powered by natural language processing reduce manual review hours and help compliance teams respond promptly to changing rules.
Energy
Demand forecasting and grid optimization models use big data from sensors and meters, enabling energy companies to balance load, reduce waste, and plan infrastructure investment.


Transparency at each stage
Discovery & Alignment
Defined goals and a precise roadmap ensure your vision is realized without unexpected pivots or hidden costs.
Technical Strategy
Senior engineers select the optimal tech stack with clear architectural reasoning for long-term scalability.
Iterative Development
Gain real-time access to code and staging environments with regular demos to track every milestone as it happens.
Careful Testing
Receive transparent QA, security, and performance audits to ensure a flawless and stable launch every time.
Deployment & Support
Stay in total control with full documentation and proactive monitoring to keep your systems running at peak performance.
Numbers Don’t Lie
Recent projects showcasing how we design, engineer, and deliver production-ready software solutions.

- Startup
- Real Estate
Our Haus AI
A finance professional turned founder built Our Haus AI, an AI-powered collaborative workspace where homeowners and contractors scope, bid, contract, and document renovation projects together. SoftDoes took her prototype and made it production-ready.- 10XMVP scope delivered
- 2+years Ongoing partnership
- 1Fully owned Platform

- Finance
- Energy
Deepwater Insights
Deepwater Insights delivers proprietary alternative data and niche research on the offshore drilling and energy sector to institutional investors, family offices, and high-net-worth individuals who require coverage that larger firms don't provide.- 100%Brand Continuity
- 2Platform Distribution
- 100%Paywall-Ready Content

- Real Estate
The building buyer
The Building Buyer is a Florida-based real estate investment firm co-founded by Dylan Troiano and Charles Hanlin. They acquire single-family, multifamily, and commercial properties across South Florida and beyond, with a focus on motivated seller opportunities.- 18Weekly hours saved
- 2+Years Ongoing partnership
- 1Fully owned Platform

- Education
- Non-Profit
WOVEN & NICE
Woven is a Spring Valley, NY nonprofit running the NICE program (New Training Inclusive Community Environment) in four Rockland County schools. Their team supports students through restorative practices, mediation, and professional development for teachers and administrators.- 4Schools Served
- 4Weeks to Launch
- 1STTime on Upwork

- Healthcare
CareInTouch
CareInTouch is a Bay Area home health agency providing skilled nursing and therapy services to patients referred from hospitals and clinics. With over 100 staff, they operate in one of the most complex and compliance-driven healthcare markets in the country.- 40% Reduction In Billing Errors
- 100+Staff Operations Managed
- 0Missed Compliance Deadlines

- Startup
Sparkle The Cleaning Service
Sparkle The Cleaning Service is a Detroit-area residential cleaning company with 10 years in business, connecting homeowners with vetted, insured independent cleaners through a subscription-based marketplace platform.- 75% Platform Transparency
- 2XPlatform Growth
- 40%Higher User Retention

- Startup
DineMate
DineMate is a Maryland-based dating and connecting platform built around verified profiles, restaurant reservations, and prepaid dining experiences. Founded to bring back authenticity to how people meet and connect.- 60% Time Saved
- 99%System Reliability
- 40%Higher User Retention

- Healthcare
Prior Authorization AI
Prior Authorization AI is a healthcare automation startup building AI-powered tools to streamline prior authorization for Medicare and Medicaid medical transportation providers in New Jersey.- 16Weekly hours saved
- 63%Admin time reduced
- 43%Fewer submission errors

- Education
Grand Central Language Services
Grand Central Language Services provides translation and interpretation for organizations operating in complex, multilingual environments. As demand grew, internal workflows became harder to manage. SoftDoes built a custom platform to streamline coordination, improve visibility, and support scalable operations.- 72%Workflow Reduction
- 48%Coordination Reduction
- 83%Visibility Increase

- Healthcare
FMY Orthodontics
FMY Orthodontics, a multi-location practice in West Tennessee, partnered with SoftDoes to replace a spreadsheet-based financial workflow with a custom web platform. The goal was to simplify how staff present treatment financing while allowing patients and families to review and complete decisions remotely.- 60%Workflow Reduction
- 75%Remote Adoption
- 5Locations Aligned

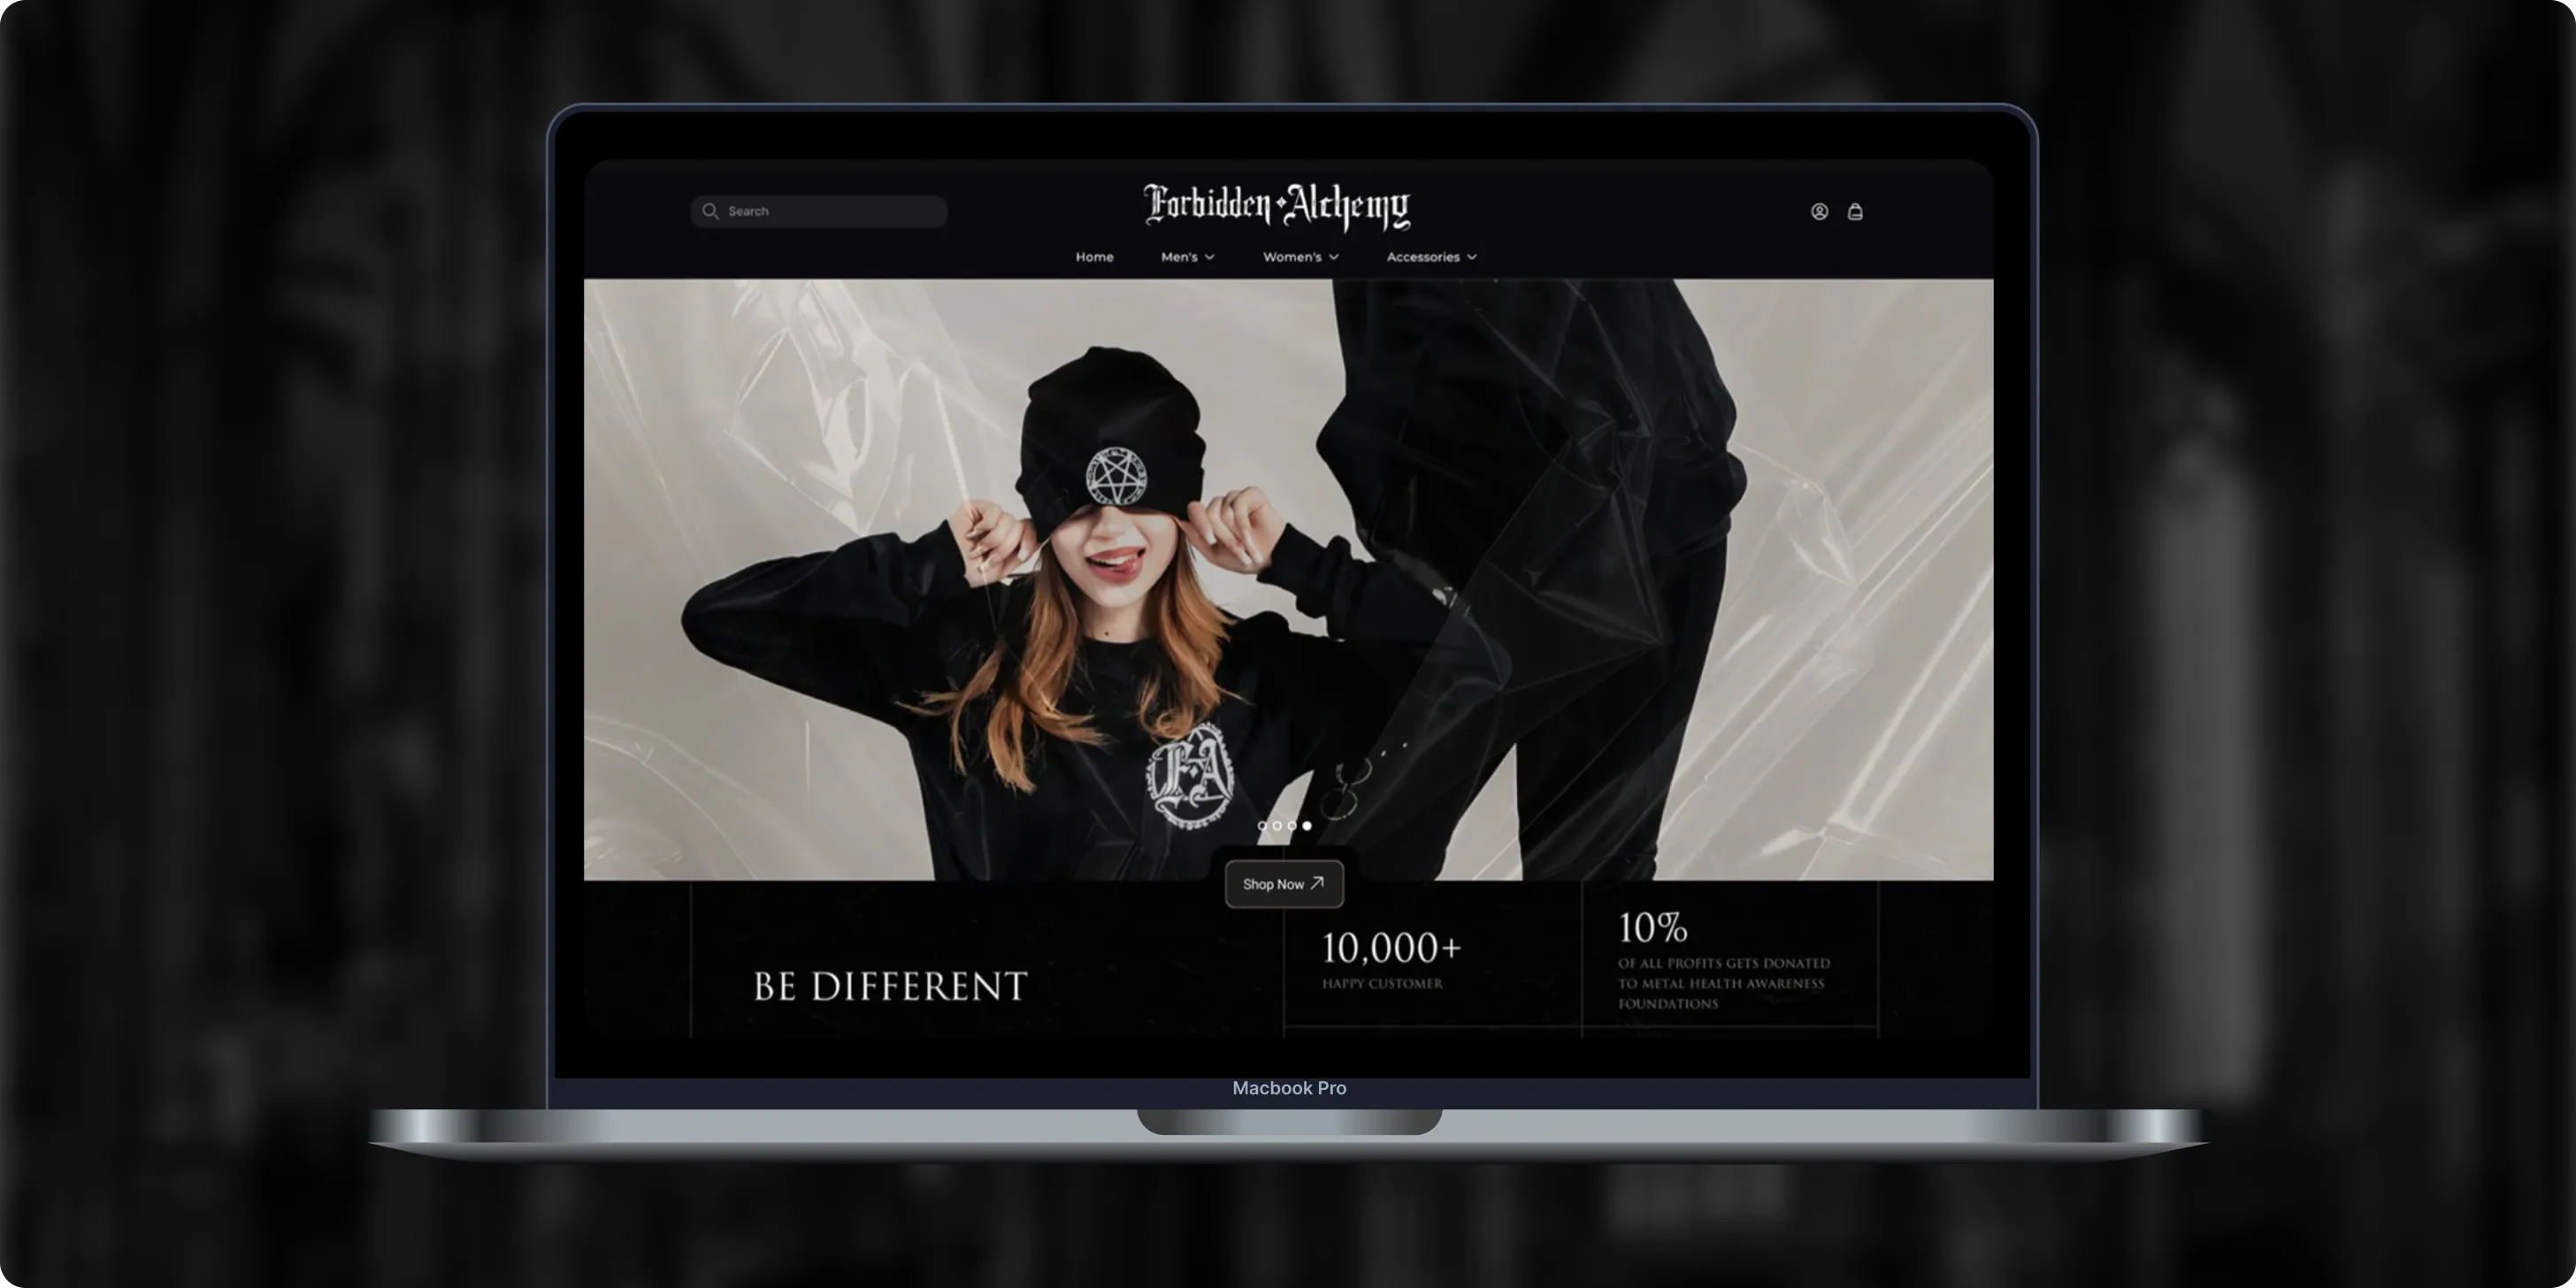
Forbidden Alchemy
Forbidden Alchemy is an alternative fashion brand creating dark, provocative clothing for the metalhead community, with 10% of profits donated to mental health awareness. Its mostly mobile audience struggled with a store that was hard to navigate and weak on functionality.- +44%Revenue Month Over Month
- 86%Design Satisfaction
- 2.8XUser Retention Growth
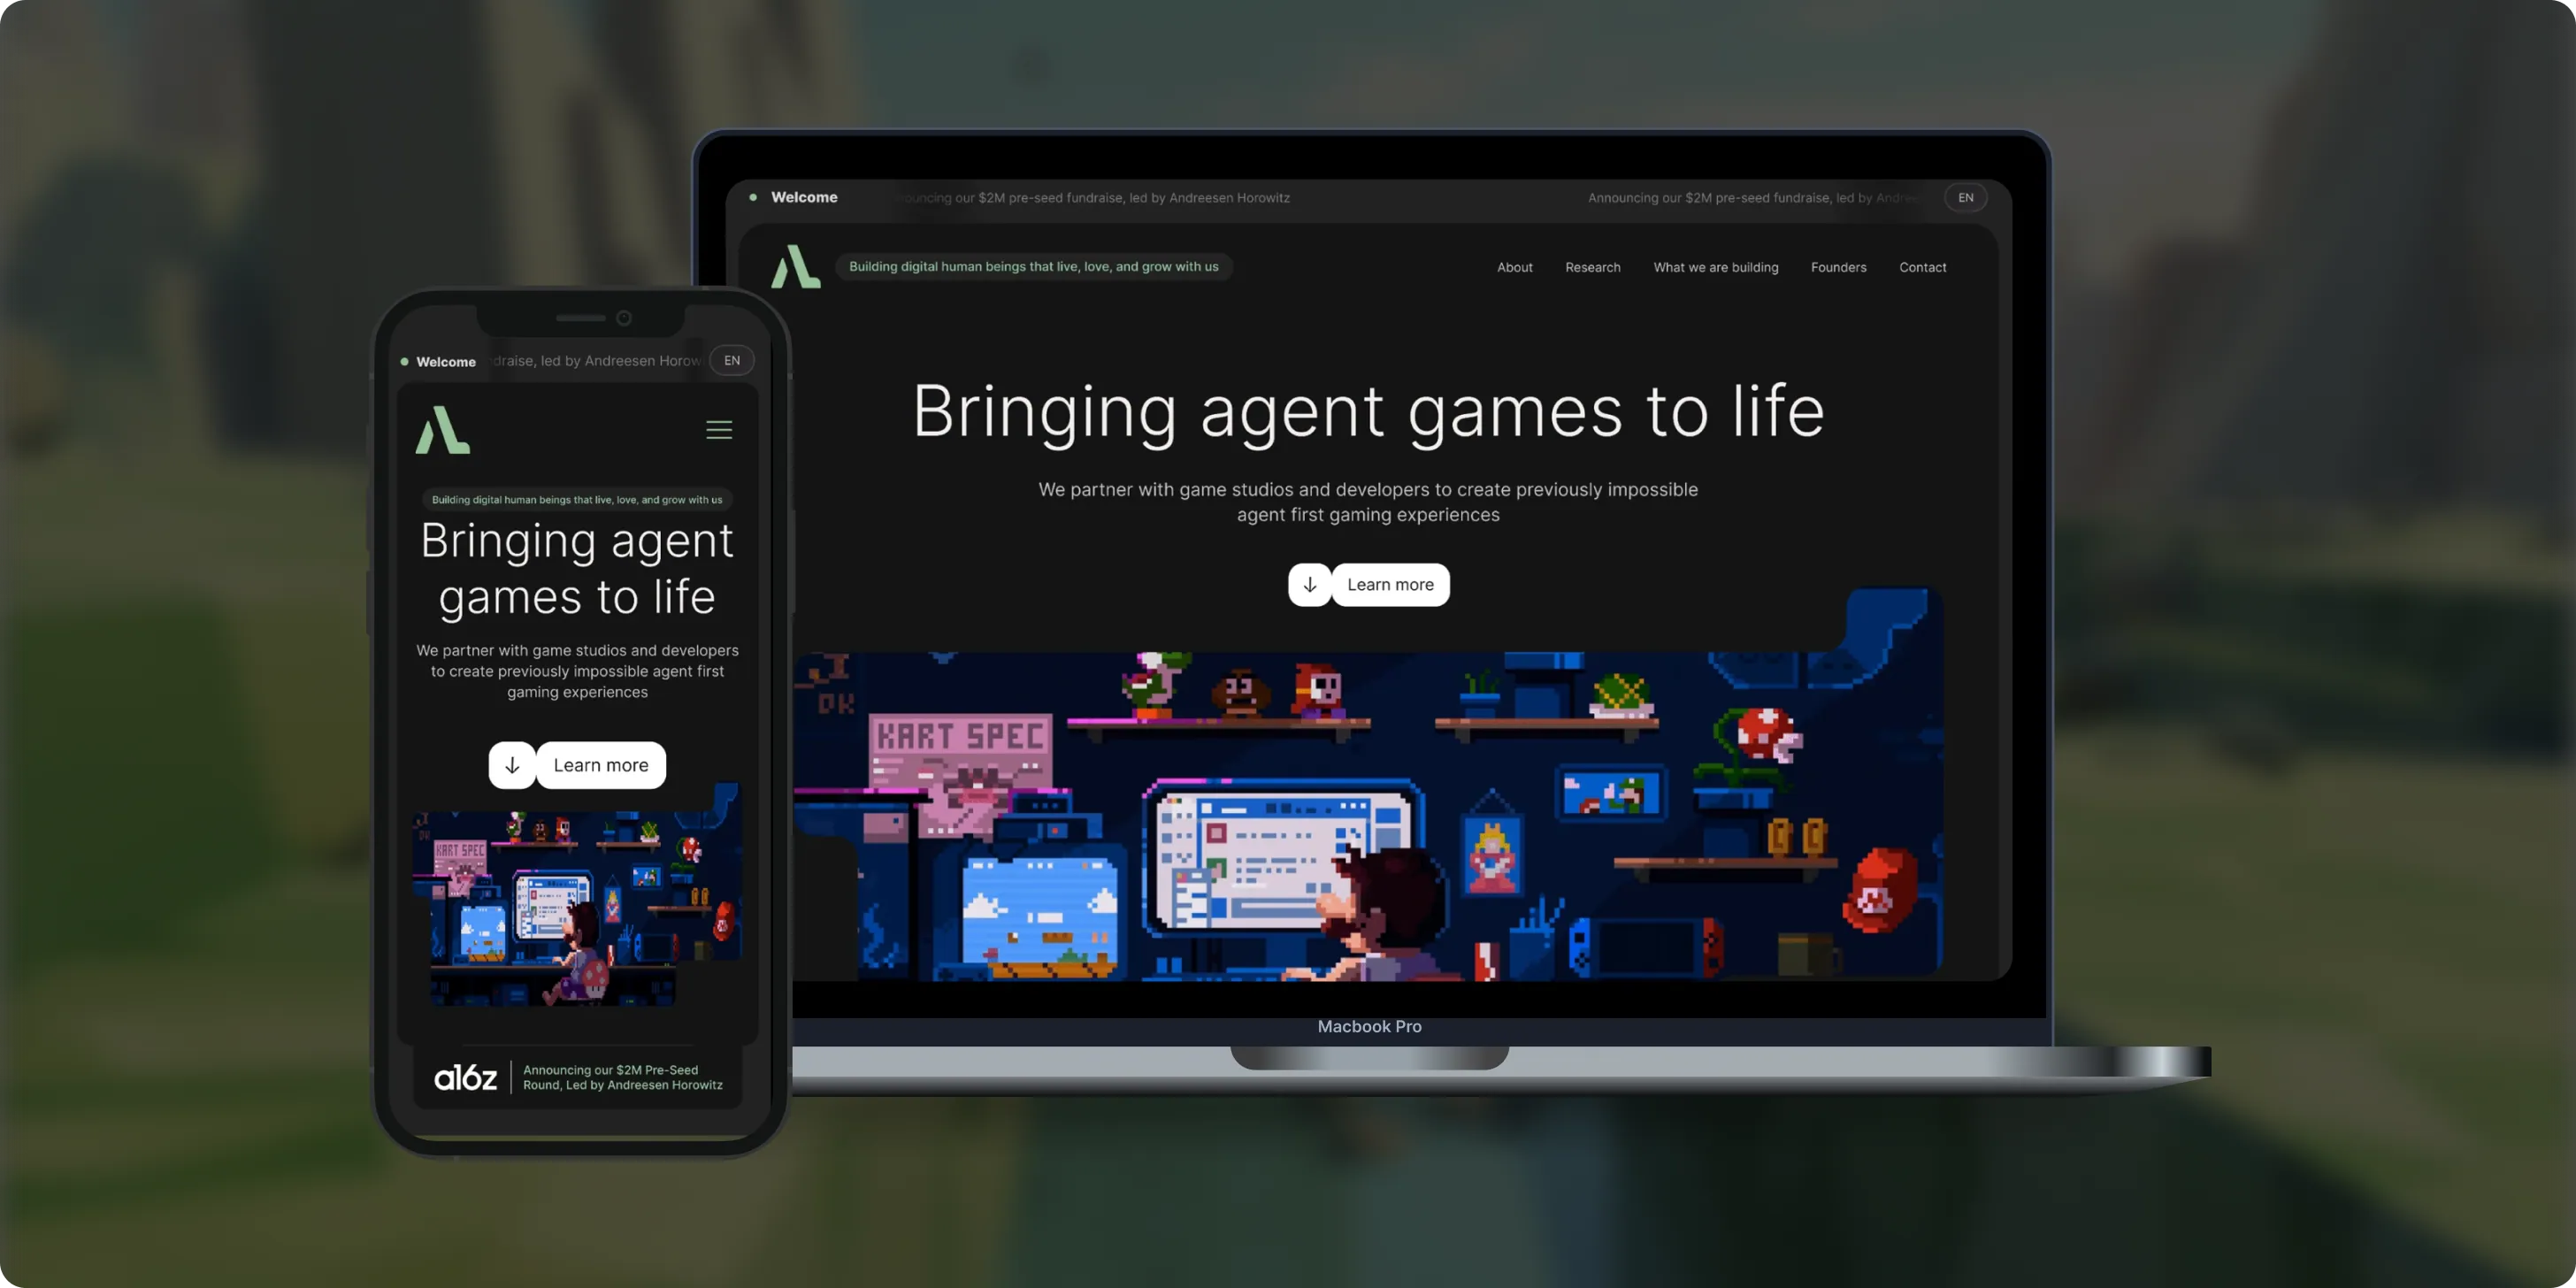
Altera
Altera builds on decades of computational neuroscience research to create digital human beings for gaming. Backed by a $2M pre-seed round led by Andreessen Horowitz, the team needed a landing page that could explain complex agent technology to players, partners, and investors.- 98%Dynamic Customization
- 100%Streamlined Navigation
- $2MPre-Seed Round
- Real Estate
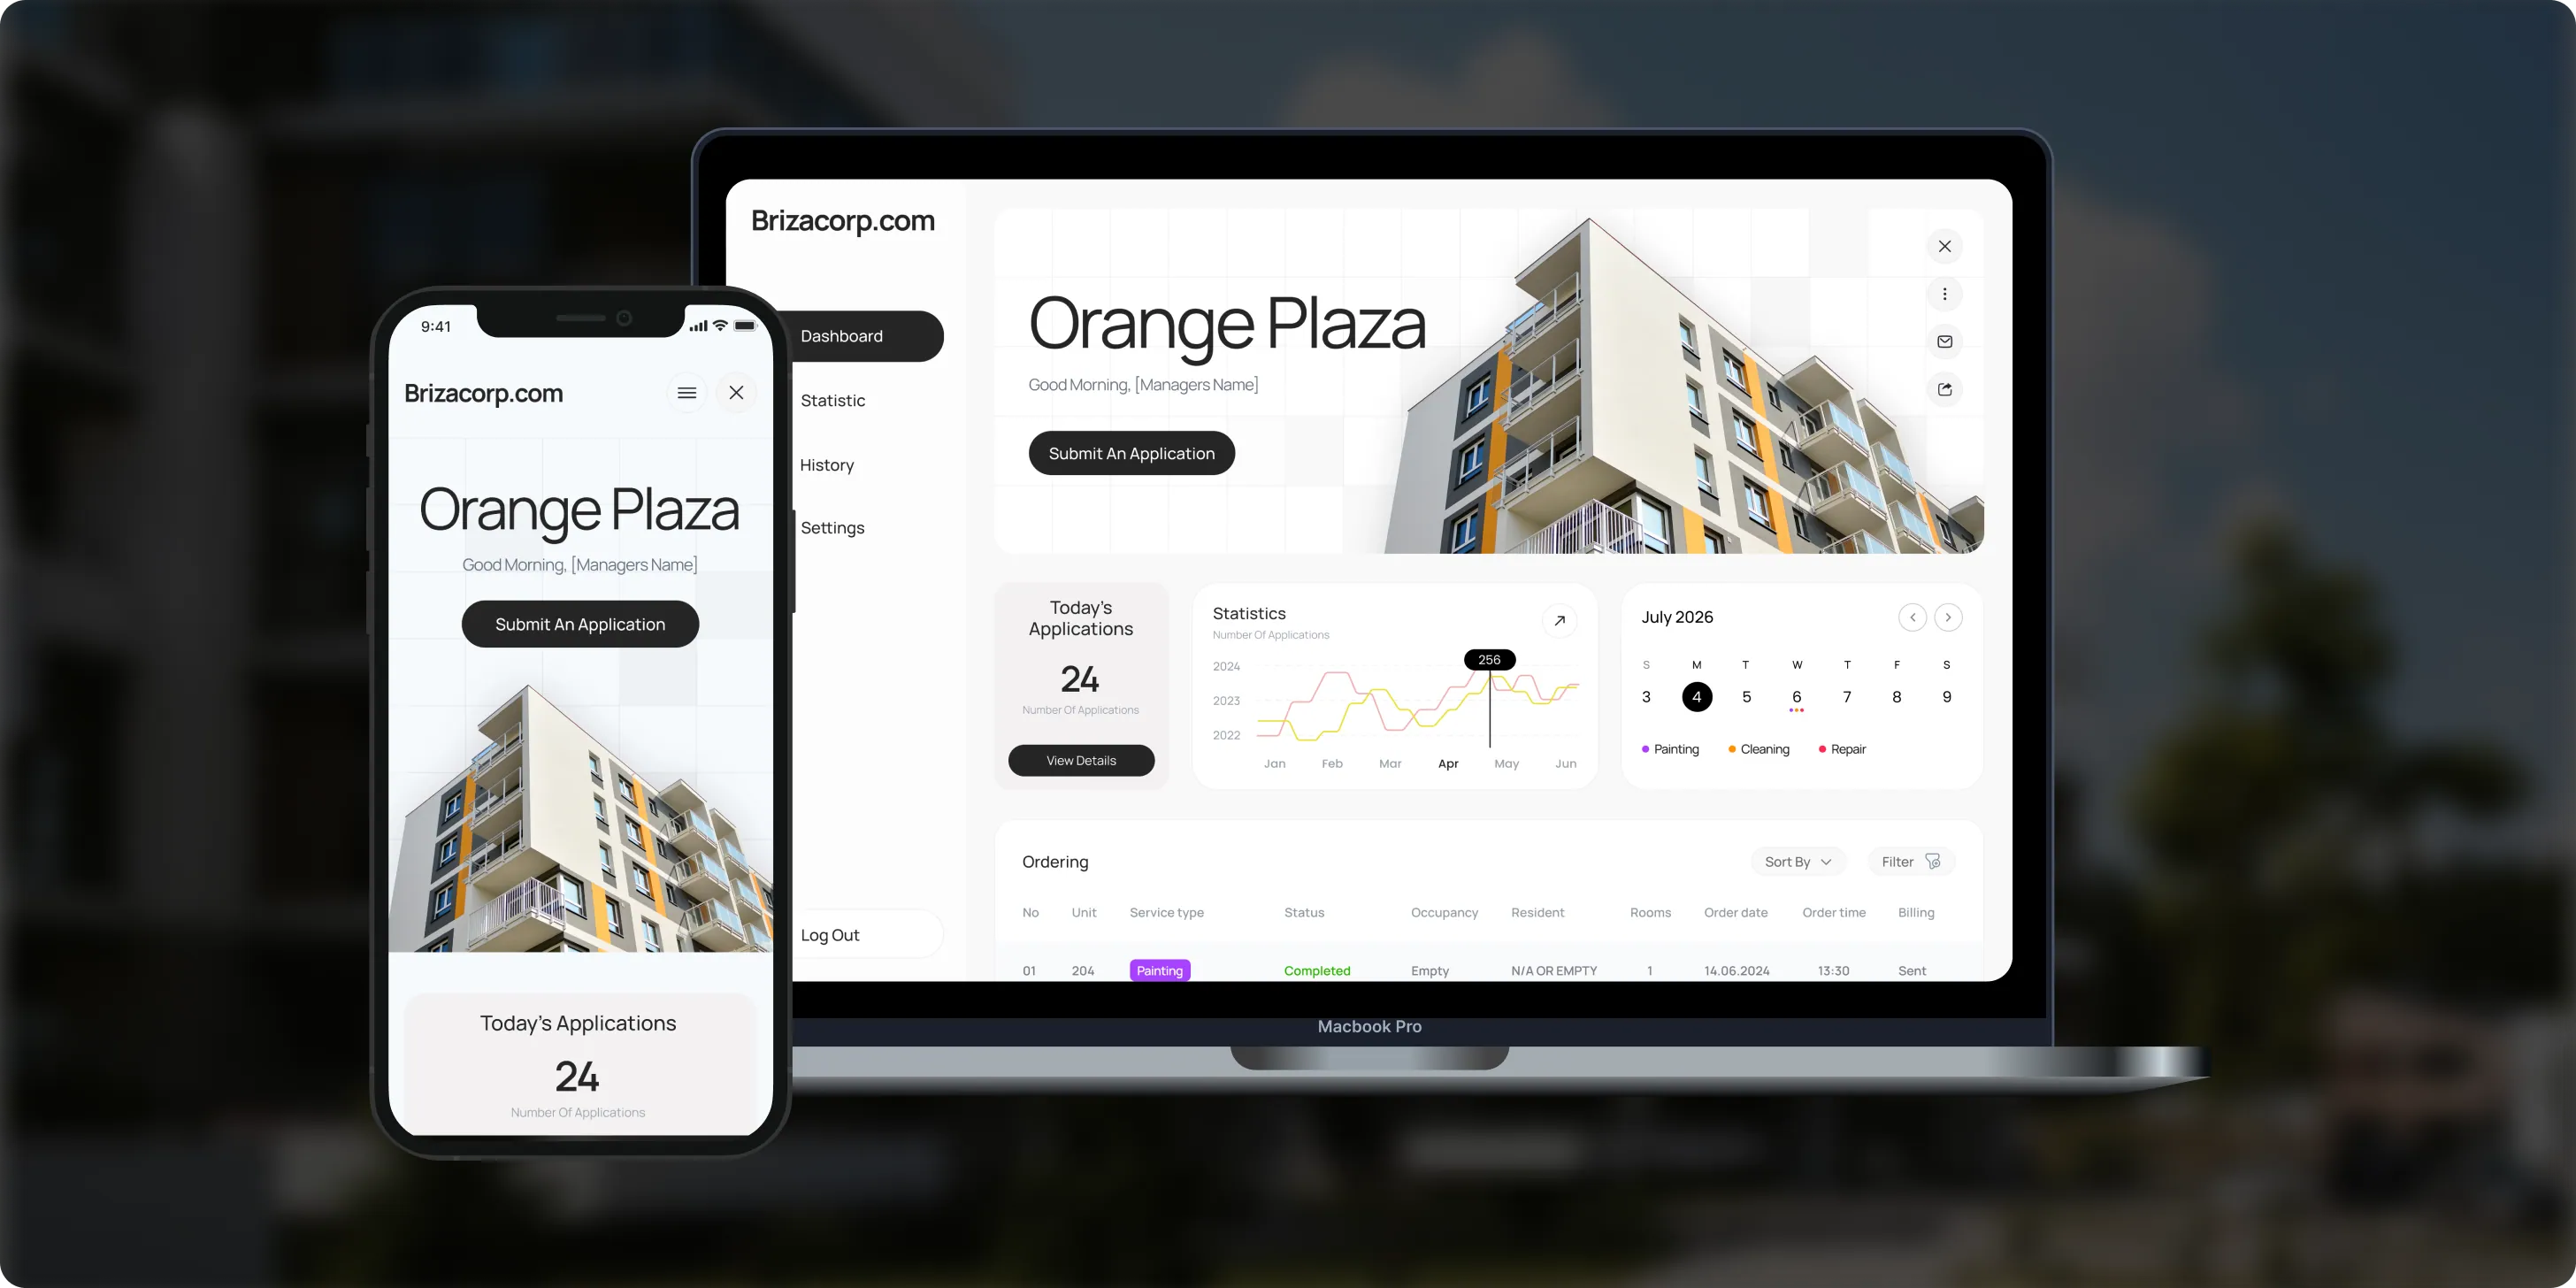
Brizacorp
Brizacorp manages residential properties and coordinates the staff who handle painting, cleaning, and repair requests. Its team tracked work across messengers, phone calls, e-mail, and paper planners, with no single place to manage requests or measure performance.- 98%Application Stability
- 95%Utilization Rate
- 30%Faster Task Completion
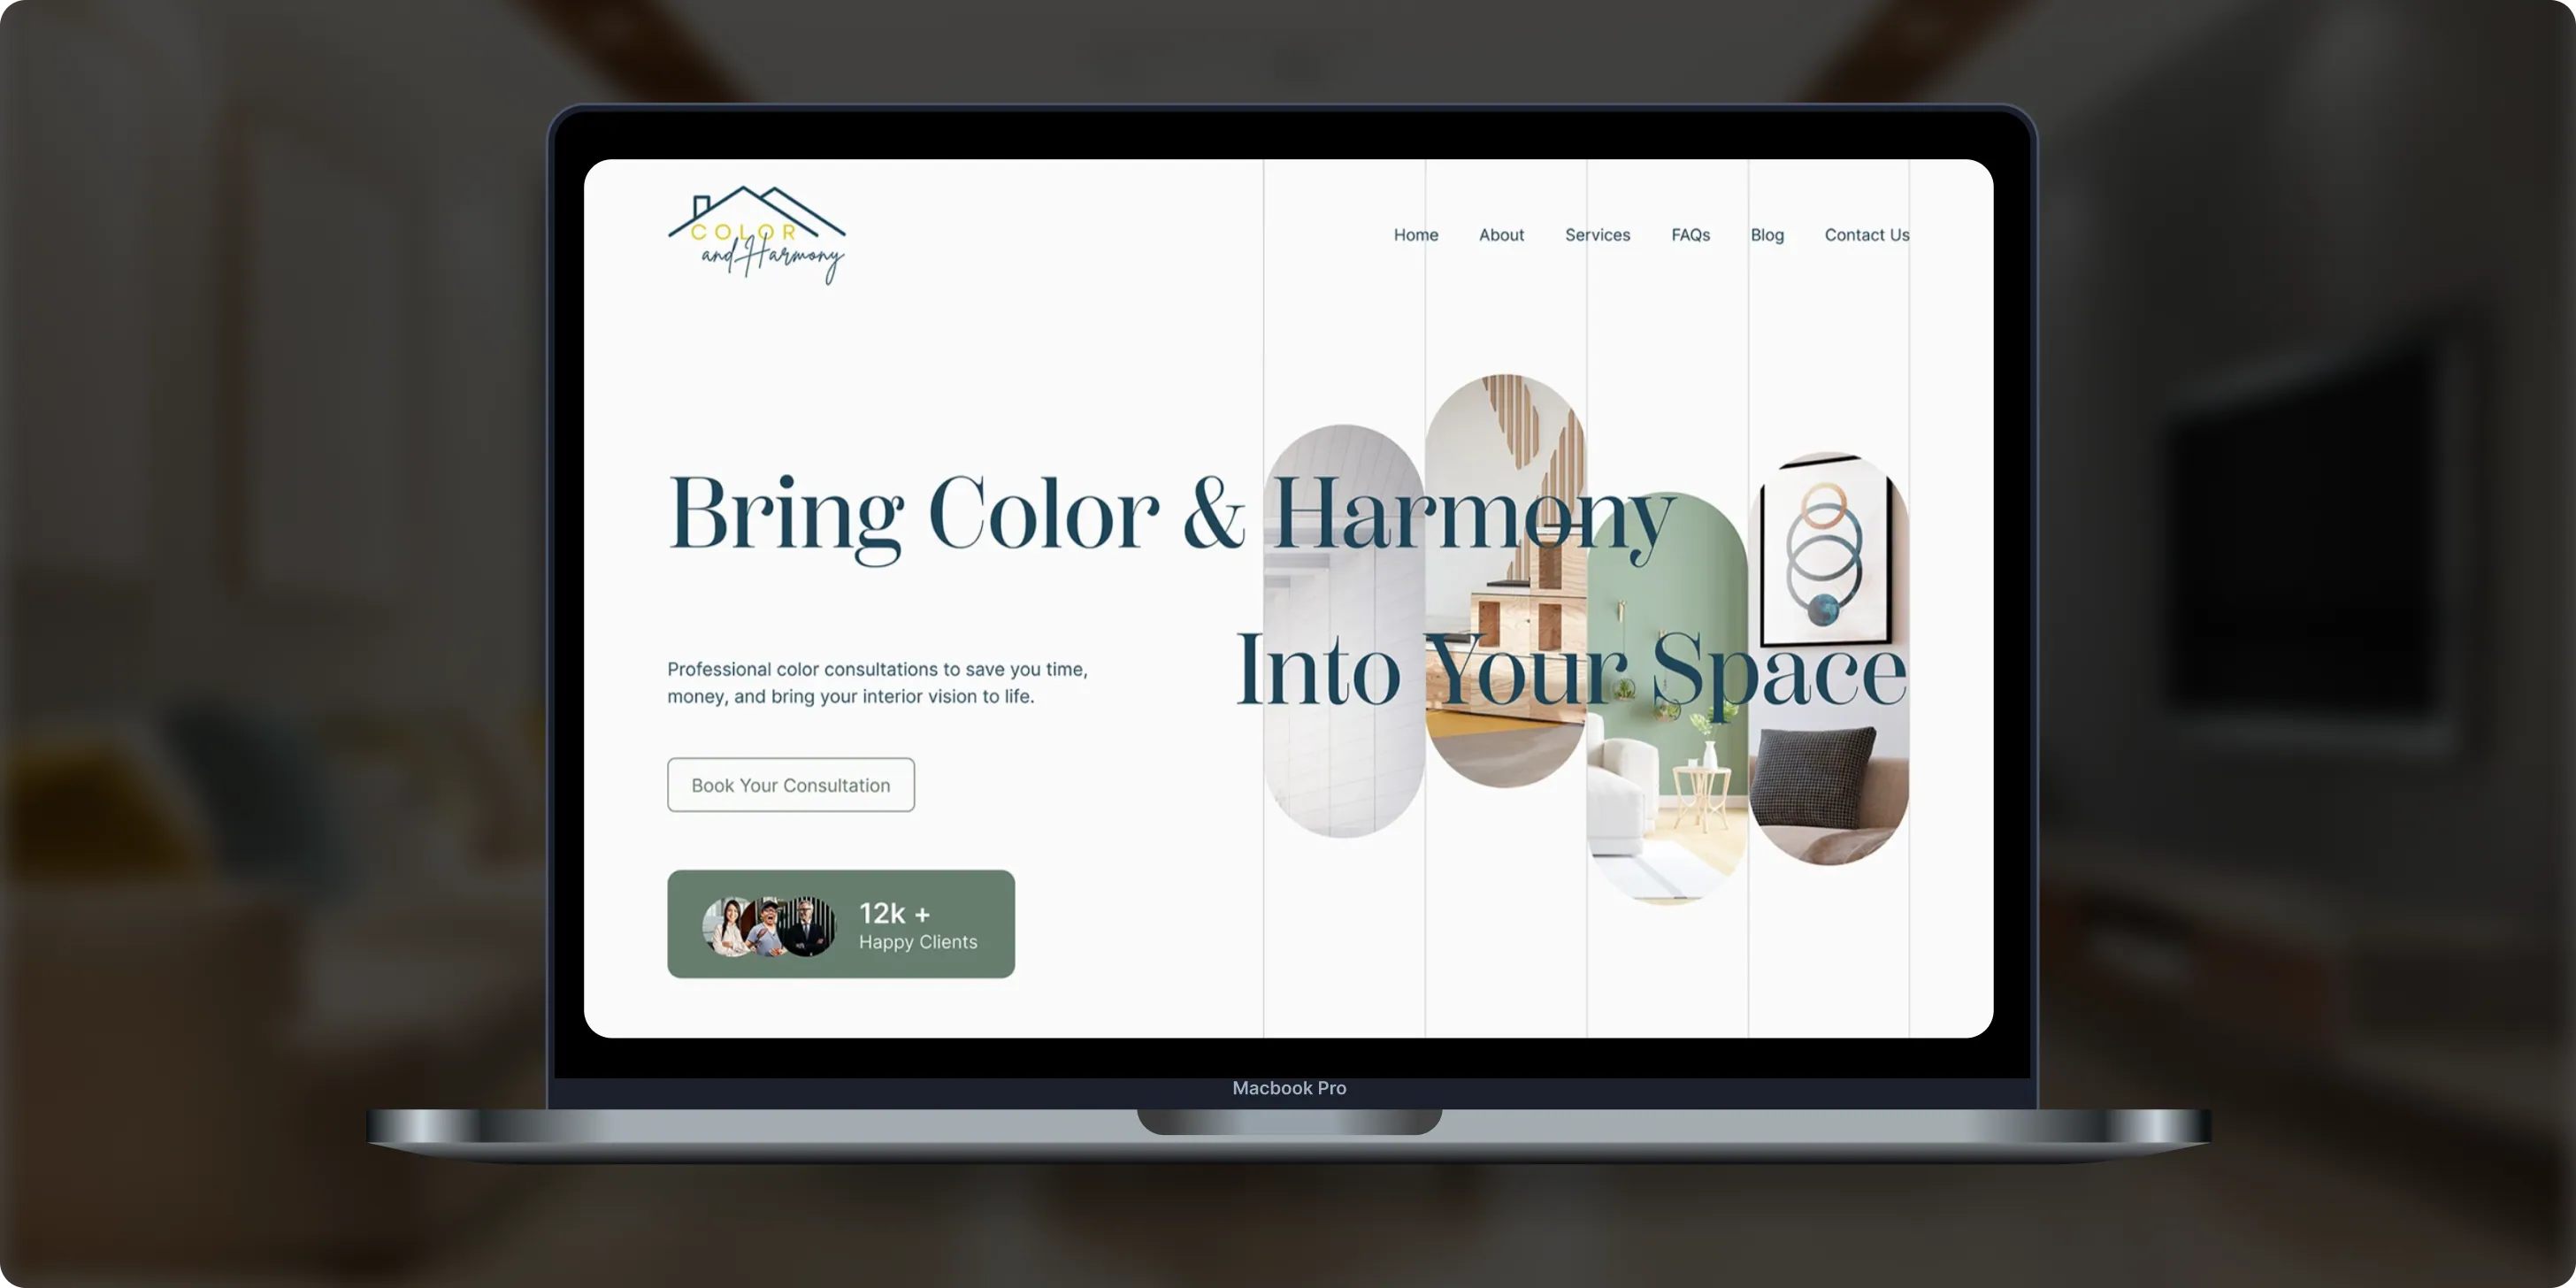
Color & Harmony
Color & Harmony is a Kentucky-based color consulting studio led by certified color strategist Diana Cartaya. The studio needed a website that reflects its refined aesthetic, showcases its portfolio, and explains a science-based color process in simple language.- 45%Conversion Rate Increase
- 50%Higher User Engagement
- 2Months to Launch
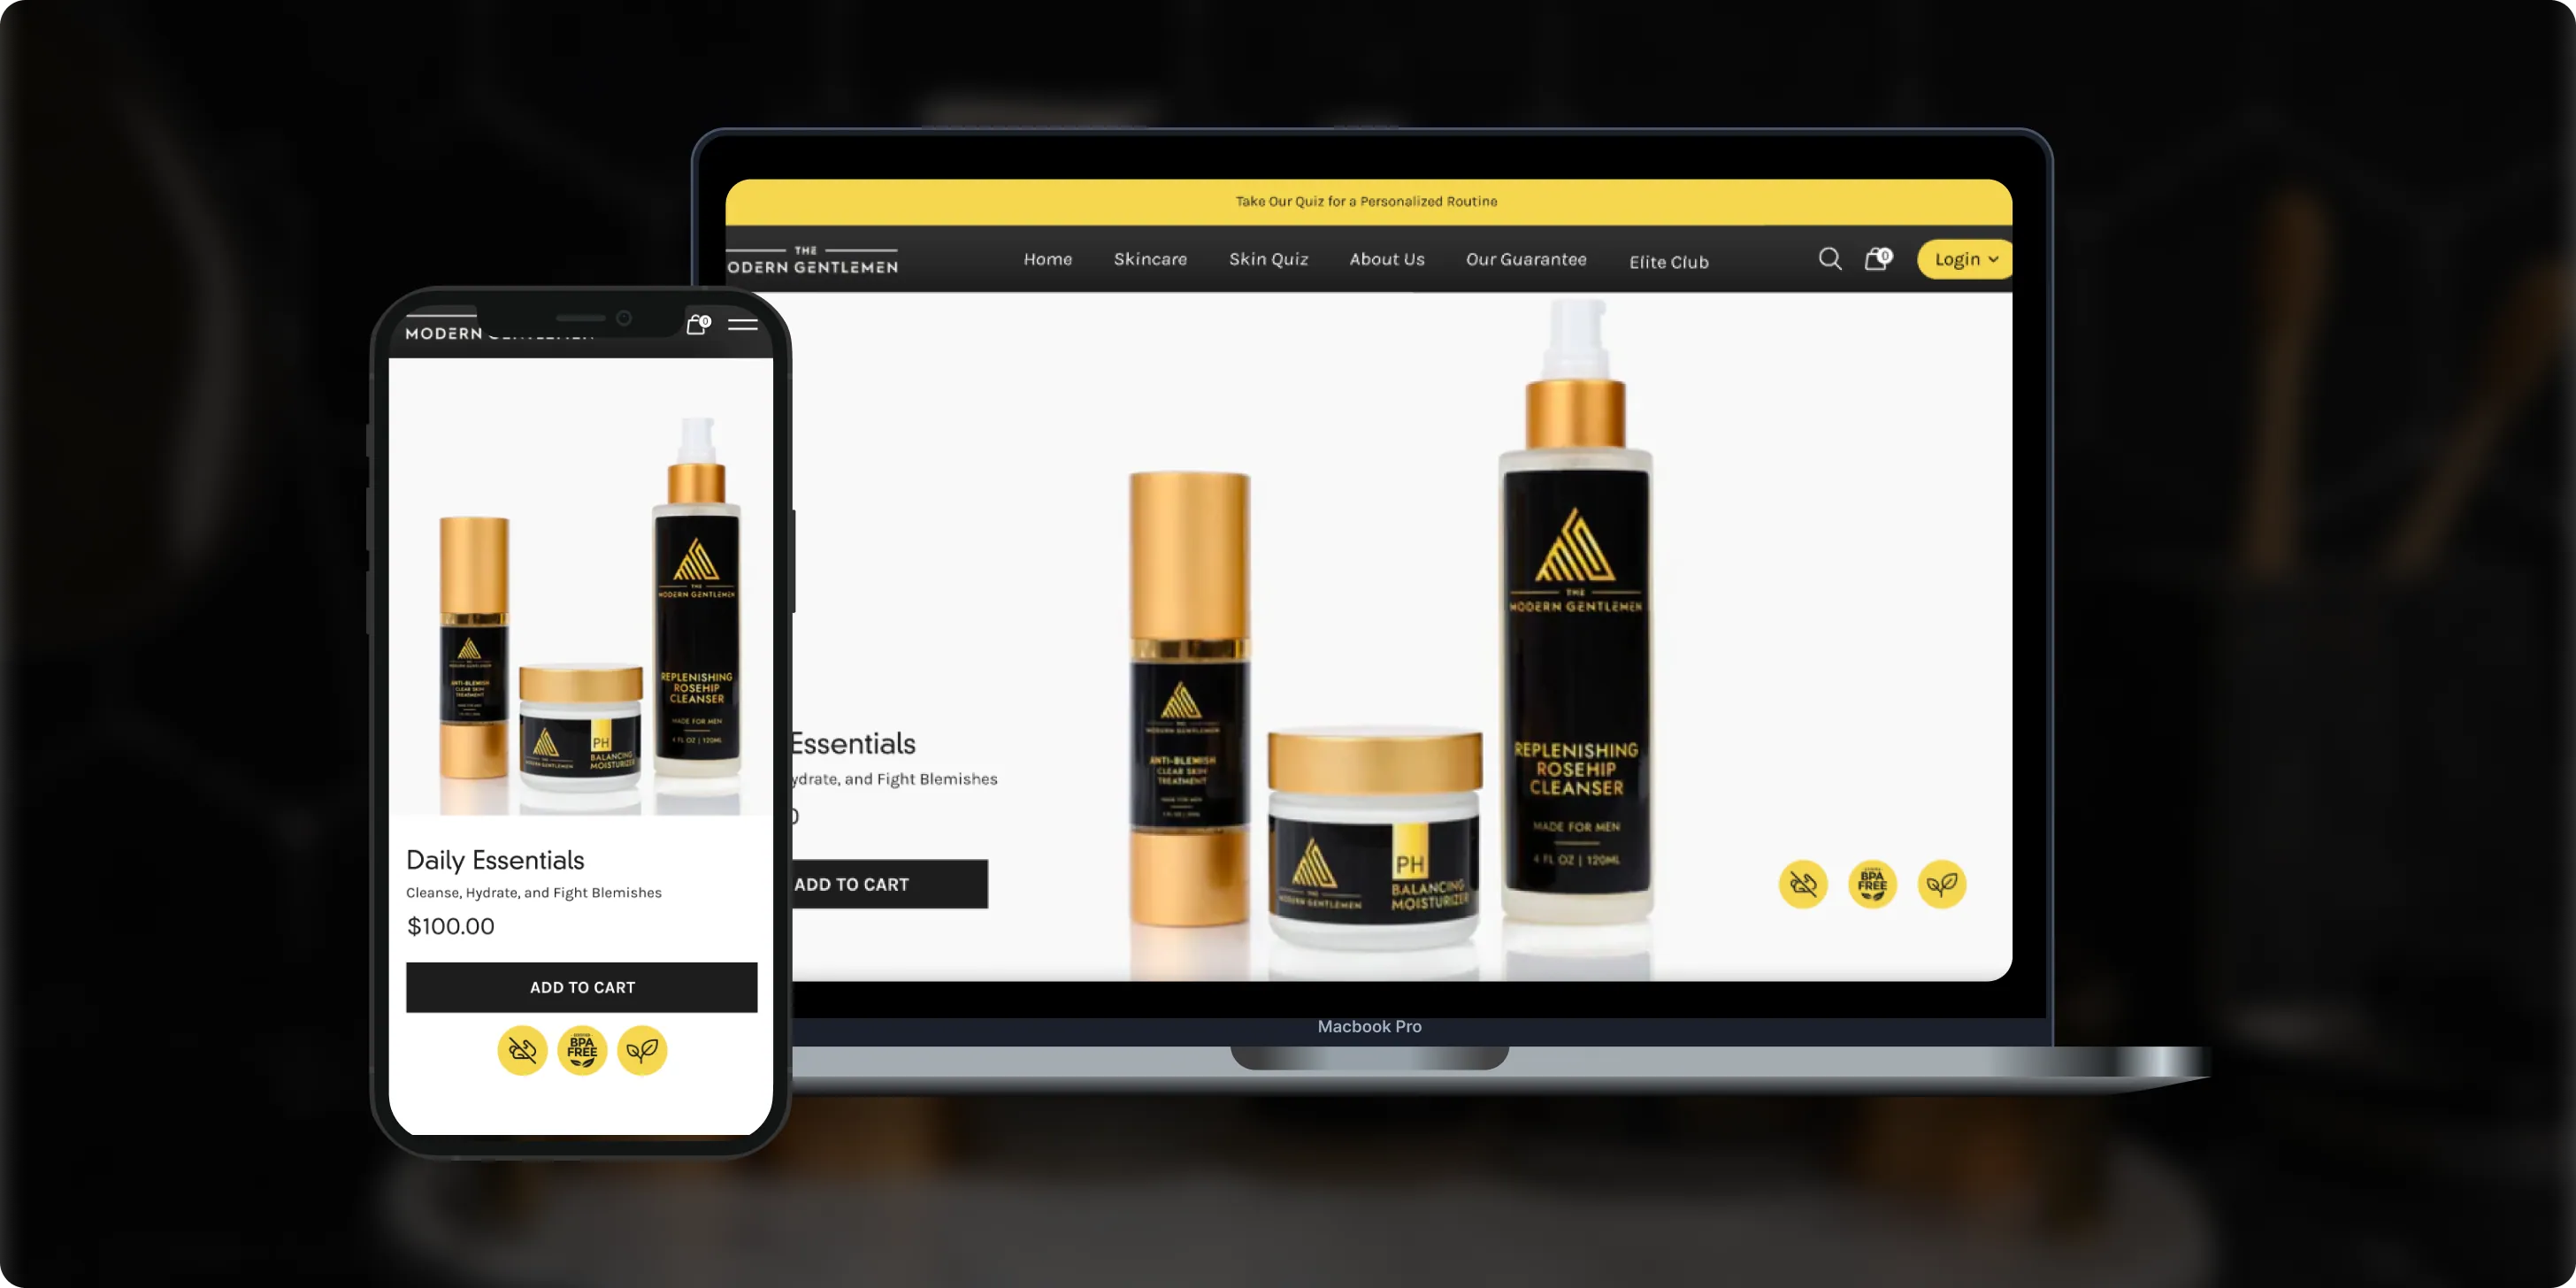
The Modern Gentlemen
The Modern Gentlemen sells premium men's skincare featured in Men's Health, GQ, and Men's Journal. Its customers wanted an efficient routine, but generic product suggestions and limited skincare knowledge made choosing the right products hard.- 30%Increase in Conversions
- 25%Higher Customer Retention
- 92%Mobile Purchases
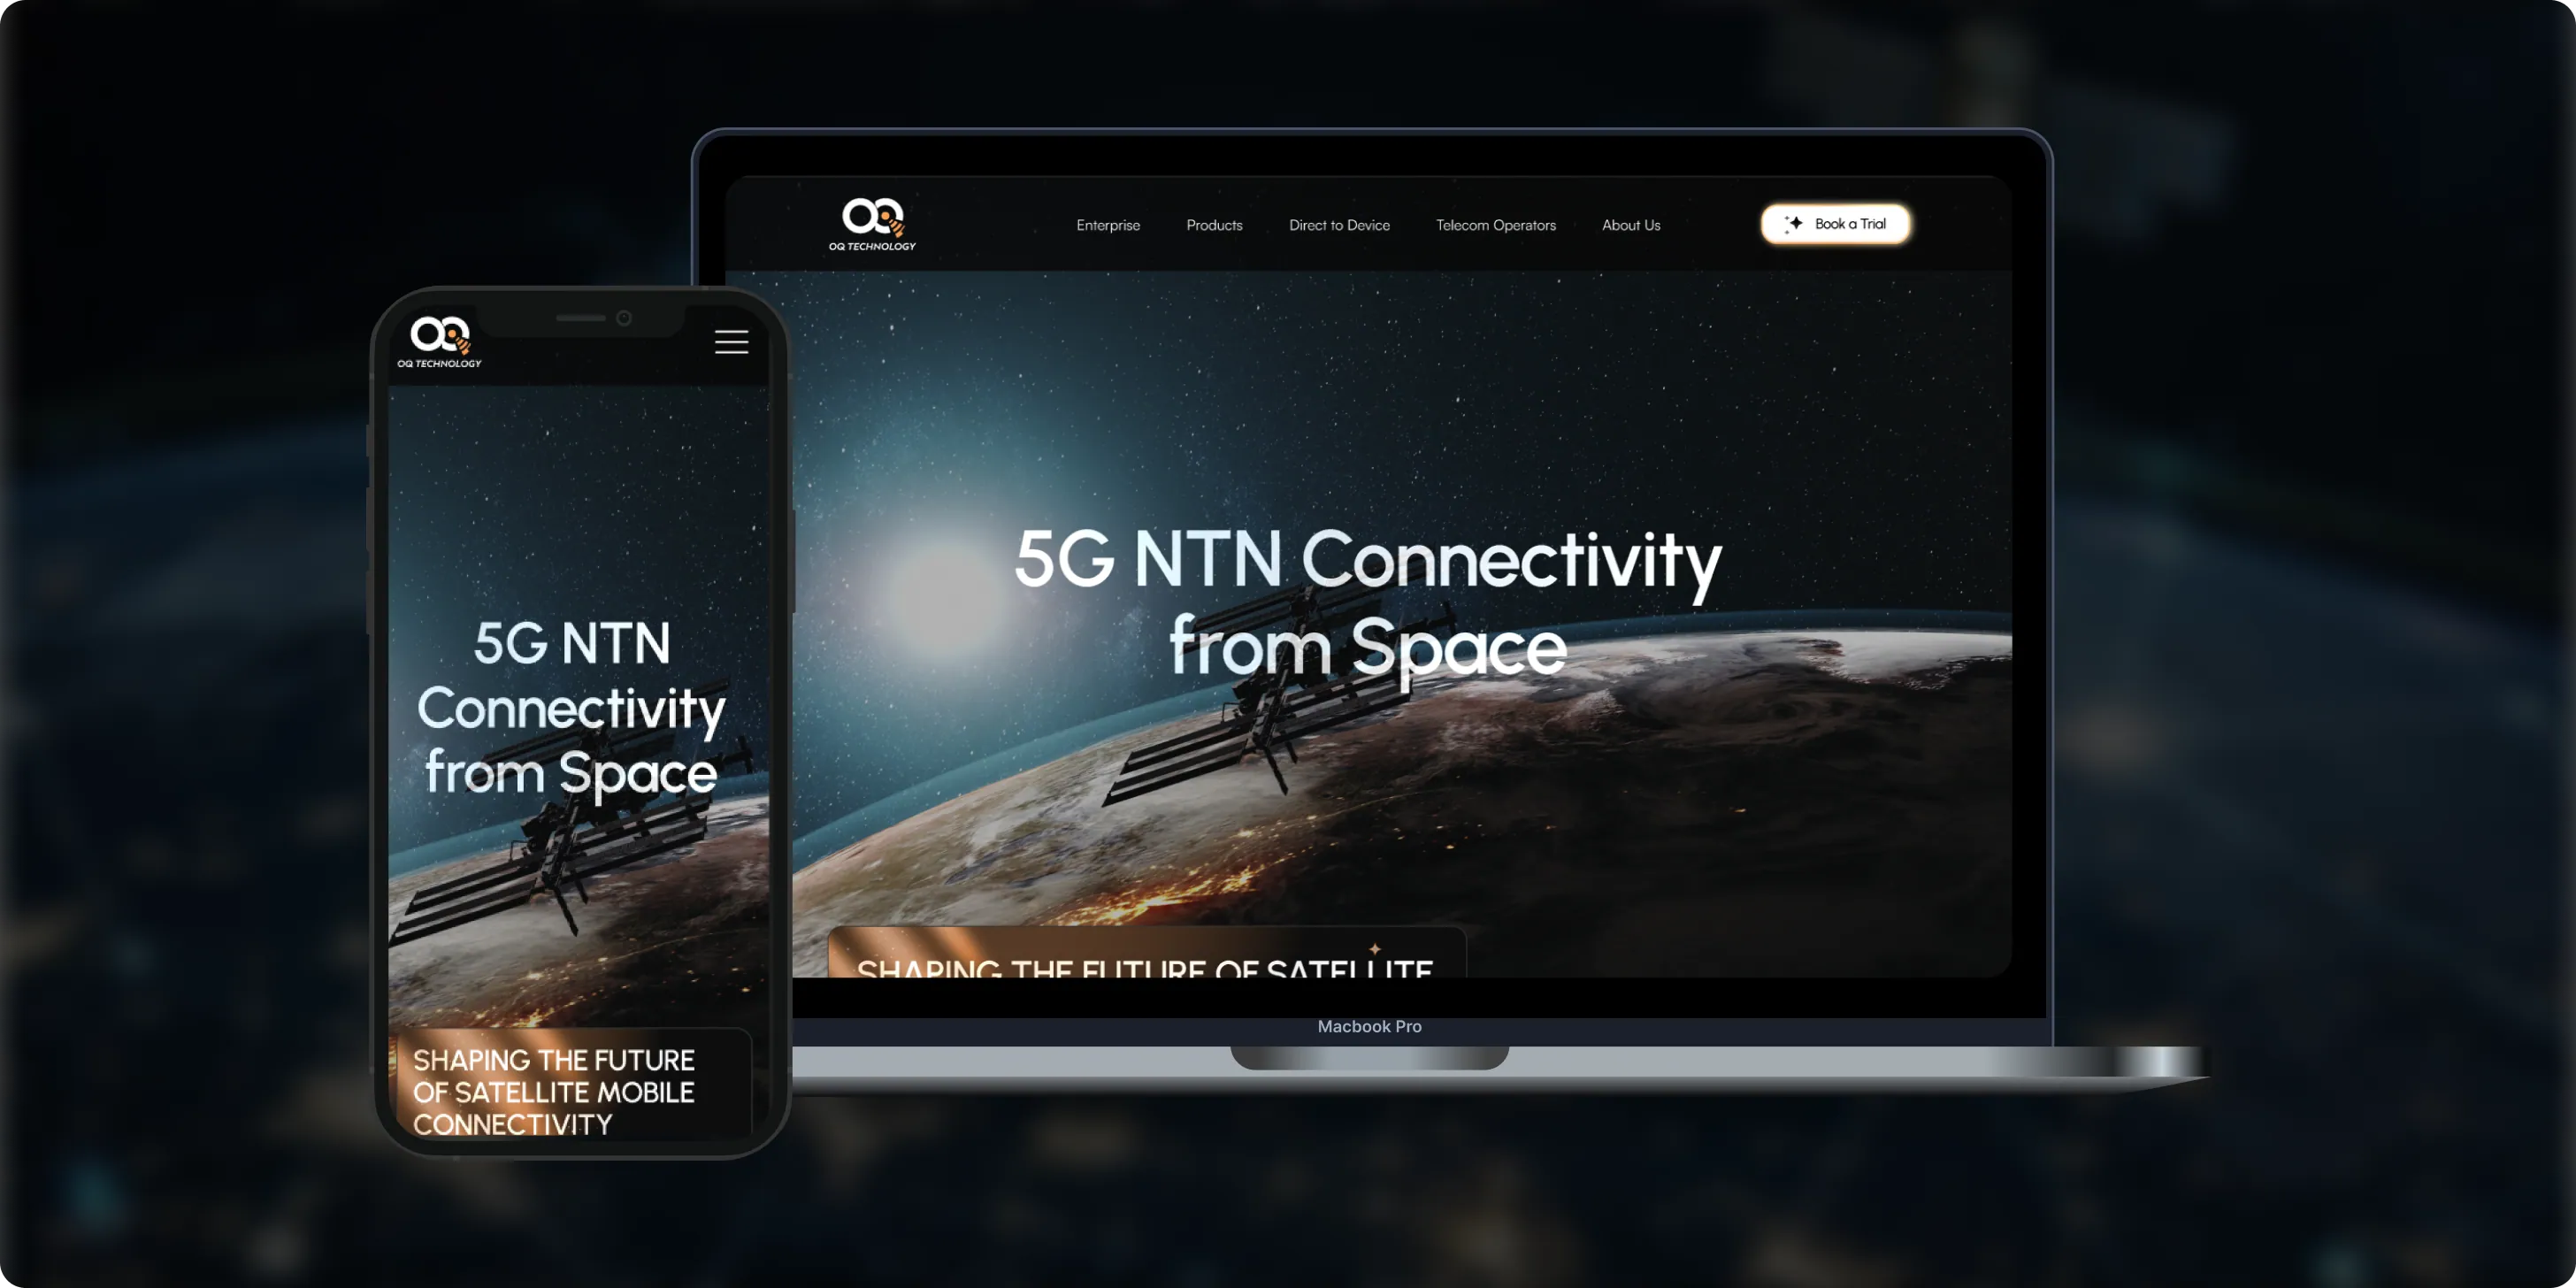
OQ Technology
OQ Technology connects IoT devices, machines, and people anywhere on the planet through its satellite network, serving energy, maritime, logistics, agriculture, and mobile operators. Its website made it hard to explore products and reach pricing plans.- 4Pricing Plans Clarified
- 3Dedicated User Flows
- 1Unified Platform
- Real Estate
- Finance
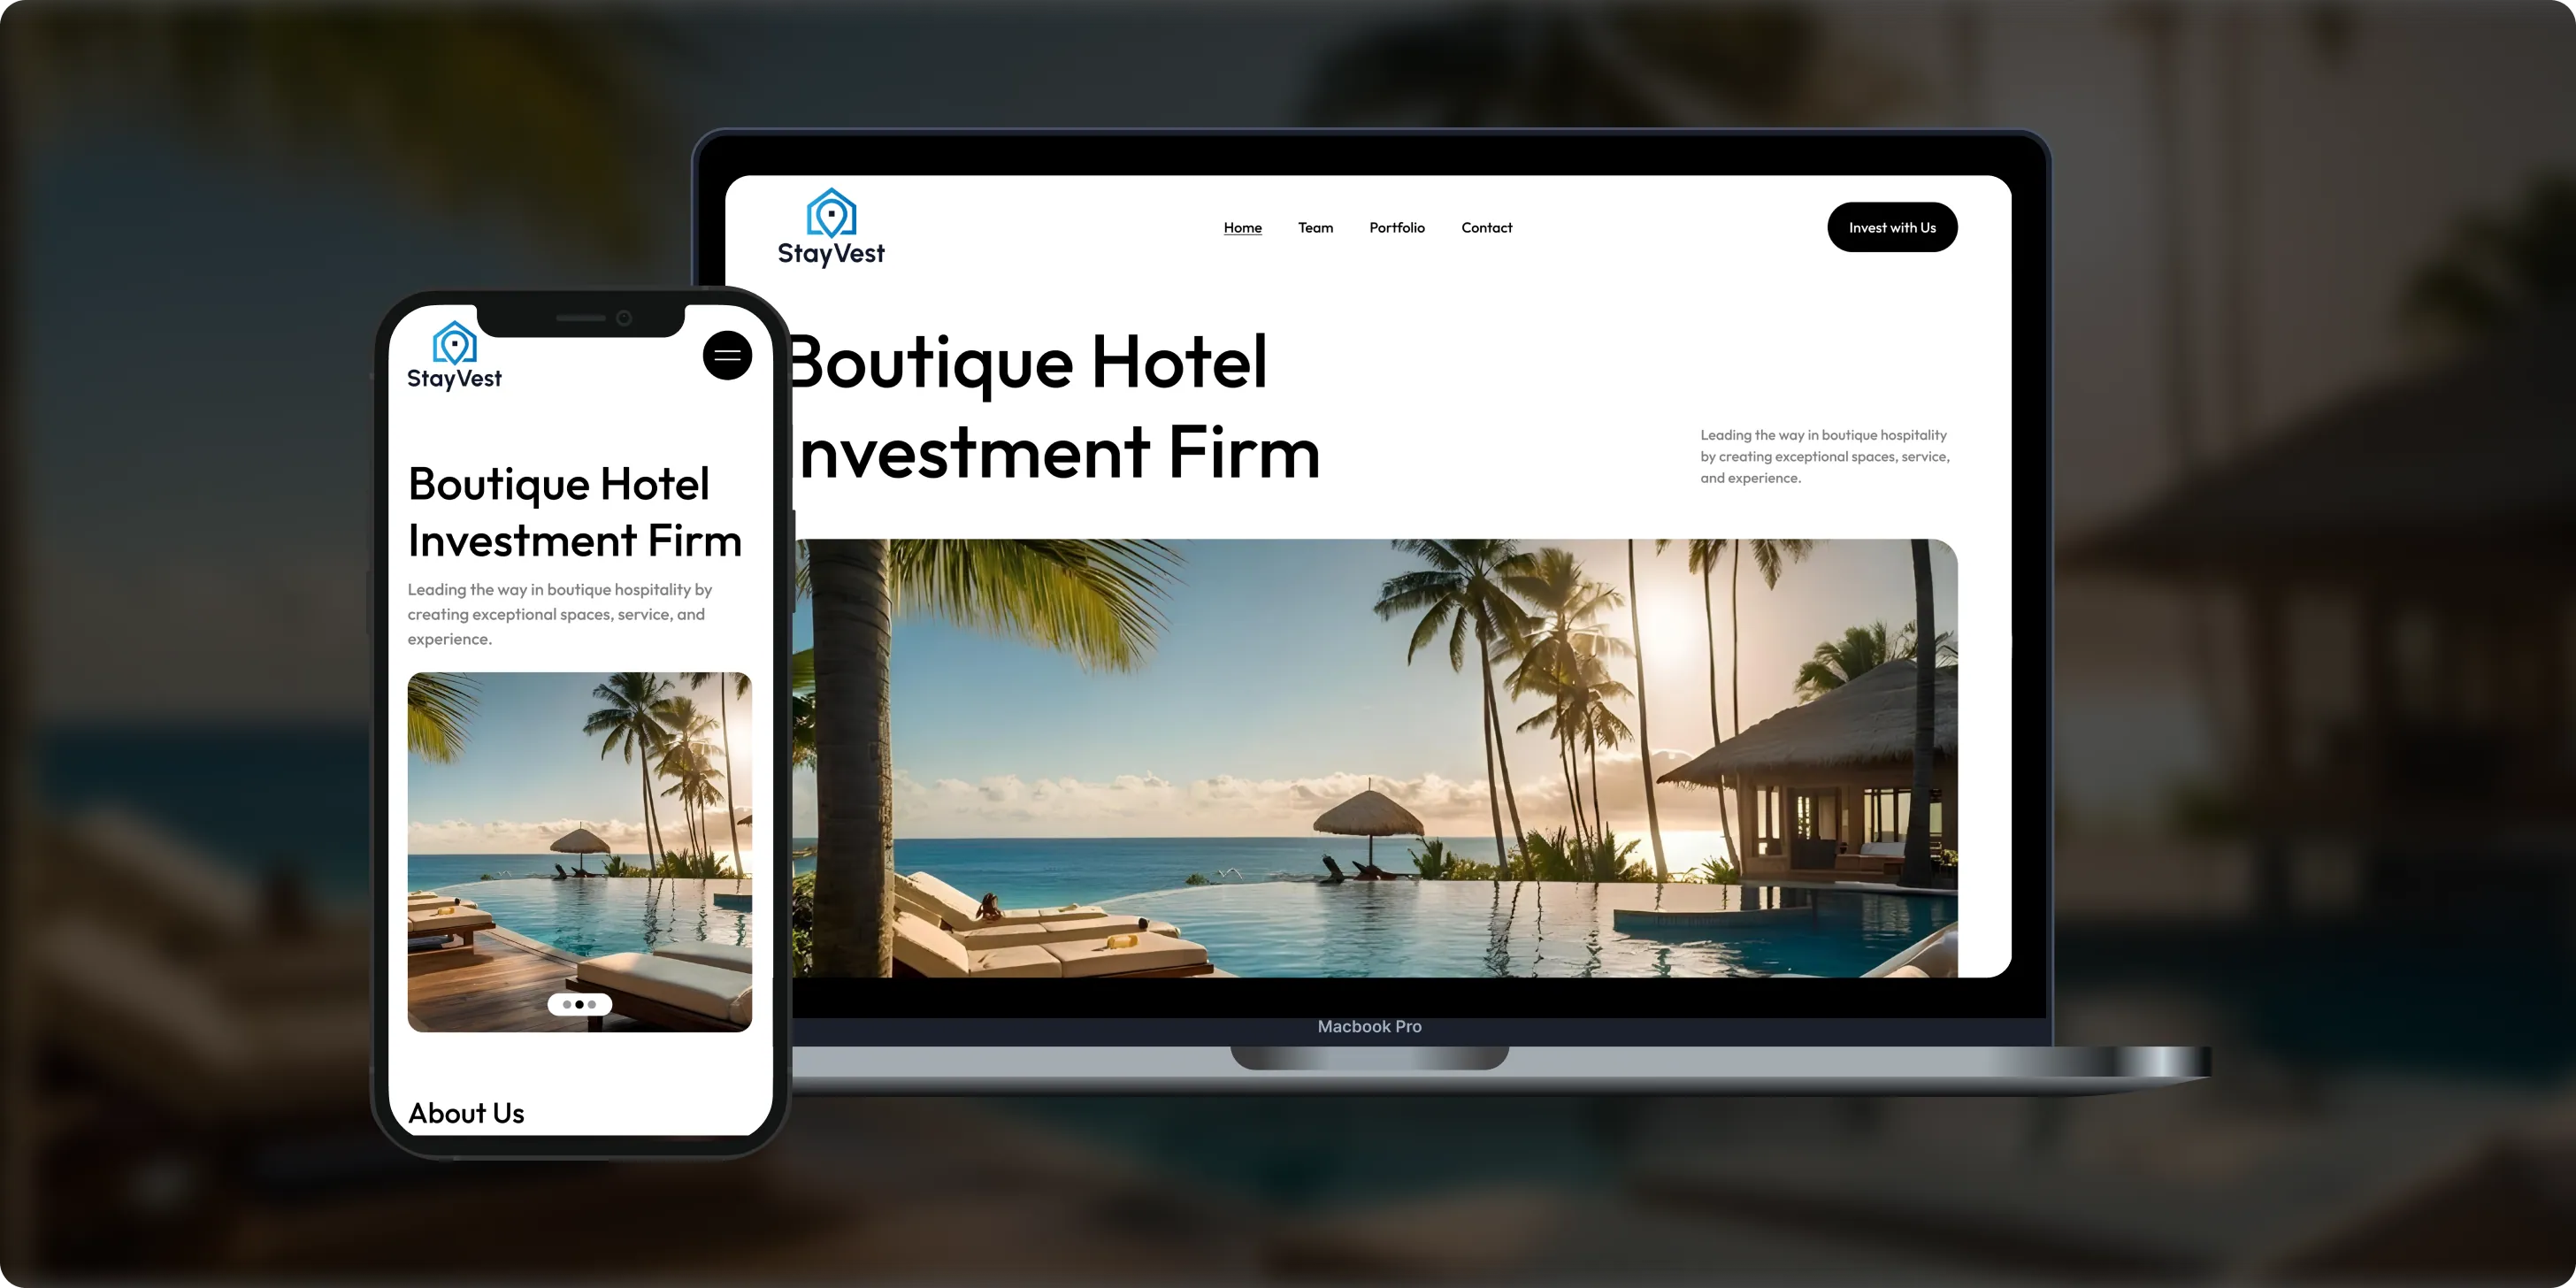
Stay Vest
Stay Vest is a private real estate investment firm that acquires, renovates, and operates boutique hotels for cash flow, tax benefits, and equity gain. It needed a platform that explains its strategy and earns the trust of passive investors.- 1,500+Guest Stays
- 200+Rooms Managed
- 5States Covered
Bokeyno Motorsports
Bokeyno Motorsports is the leading mobile installer of vertical doors for high-performance cars. This Shopify website isn’t just about services—it’s a bold statement of power, style, and expertise. With a sharp layout, strong visuals, and real-world case studies, the site delivers all the information car enthusiasts need to book confidently and instantly.- 54%Booking Requests
- 43%Lead Conversion
- 32%Qualified Inquiries

ai document processing platform
A comprehensive talent solution designed to help companies attract, hire, and retain top talent more effectively. The platform combines AI-powered recruitment technology with employee financial wellbeing programs, enabling smarter hiring decisions while supporting employees’ financial stability and long-term engagement.- 62%Faster Processing Time
- 78%Less Manual Work
- 35%Improved Accuracy

WHAT CLIENTS SAY
Independently verified reviews from real clients on Clutch.co


Client Story
Real feedback from
FMY Orthodontics
“SoftDoes consistently found ways to make things work, added features we had not originally envisioned, and never became frustrated. It felt like working with a true partner who cared about the success of our practice.”
Dan Merwin
DDS, MS, President, FMY Orthodontics

Client Story
Real feedback from
Prior Authorization AI
“Every time I sent a request, if there was anything that didn't work, they were able to turn it around quickly. Even when there were no updates yet, they always reached out to let me know they were working on it.”
Joseph Oluwo
Founder of Prior Authorization AI


Client Story
Real feedback from
WOVEN
“What stood out most was their commitment to understanding our needs before presenting solutions.”
Danna Pastran
Administrative Operations Manager, WOVEN

Client Story
Real feedback from
Grand Central Language Services
“The site performs as intended and provides the foundation for our company's digital presence.”
Joe Goldstein
QA Manager, Grand Central Language Services


Client Story
Real feedback from
DineMate
“They go above and beyond.”
Eric Snead
CEO, DineMate "Dating Connecting Platform"
WHAT CHANGED IN PRACTICE
Clients didn’t stay because of promises. They stayed because delivery became predictable, ownership was clear, and the product kept moving forward after launch.
- 01Direct Access to Senior Engineers
Every project is staffed with senior engineers who participate in technical discussions directly with your team. There are no account managers relaying messages or junior developers learning on your budget. Our data scientists and ML engineers have hands on experience shipping AI products across dozens of domains. You get direct access to the people writing your code and training your models. Questions get answered in hours, not days. That direct line means faster iteration and fewer misunderstandings.
- 02Predictable Delivery
We commit to realistic timelines and hold ourselves to them. Each project follows a structured sprint cadence with clear milestones and weekly demos. You always know what was completed, what is in progress, and what comes next. There are no surprise delays hidden behind vague status updates. If something changes, we flag it immediately and adjust the plan together. Predictable delivery is not a slogan for us; it is how we keep clients and how we keep projects on track.
- 03Built to Last Past Launch
A model that works on launch day but degrades within weeks is not a finished product. We engineer ML systems with long term performance in mind, including monitoring, automated retraining, and clean documentation. Our code is modular and maintainable so your internal team or future partners can extend it without starting over. We think about data drift, infrastructure costs, and version control from the start. Robust MLOps practices are woven into the architecture, not bolted on after the fact. The system we hand off is designed to run reliably for years.
- 04No Babysitting Required
Our teams operate autonomously within agreed boundaries. You set the priorities and we execute without requiring constant direction or follow up. Automated alerting, comprehensive logging, and self healing pipelines mean your AI systems require minimal oversight once live. We surface issues proactively rather than waiting for you to notice something is wrong. Status reports arrive on schedule without you asking for them. Your time stays focused on your business, not on managing ours.
Technologies We Use


Frequently Asked Questions
Everything you need to know about working with SoftDoes. Can’t find an answer?
Can we run our own LLM instead of renting tokens?
Yes, you can run your own open-weight LLM on your servers or cloud GPUs instead of paying per token, but you take on hosting, updates and tuning. It pays off at steady high volume or when data cannot leave your environment. Compare GPU costs with your provider's current token pricing first. San Francisco teams often mix both. Our machine learning model development team can test either setup.
What is LLM hallucination?
LLM hallucination is when a language model gives a confident answer that is false or not supported by its sources. It happens because models predict likely text rather than check facts. You reduce it by grounding answers in your own documents, asking for citations, limiting scope and testing with real questions. For San Francisco companies, our machine learning model development work can build these checks in.
How is machine learning used in insurance?
Machine learning is used in insurance to price risk, flag suspicious claims, speed up claim triage and extract data from policy and claim documents. Models can also predict which customers may not renew. They work best alongside human adjusters, who keep the final say. San Francisco insurtech startups often begin with document extraction, which starts from $5,000 at SoftDoes. See our machine learning model development.
How do you train a model with a small dataset?
To train a model with a small dataset, start from a pretrained model and fine-tune it, use data augmentation, and keep the model simple to avoid overfitting. Cross-validation shows whether results hold up, and clean, well-labeled examples matter more than volume. San Francisco startups often begin this way before their data grows. Our machine learning model development team can run a proof of concept in a few weeks.
How do you monitor ML model performance?
You monitor ML model performance by tracking accuracy against real outcomes, watching input data for drift and setting alerts when metrics fall below agreed limits. Log predictions, latency and errors, and review samples by hand on a schedule. When drift appears, retrain on fresh data. San Francisco teams can add this monitoring with our machine learning model development service.
Which machine learning projects pay off fastest for healthcare companies in San Francisco?
The machine learning projects that pay off fastest for San Francisco healthcare companies are usually document extraction, coding and claims checks, and appointment no-show prediction. They use data you already have and cut manual work quickly. Clinical prediction models take longer because they need careful validation. SoftDoes builds them with HIPAA safeguards and human review. See our healthcare software.
Can machine learning models work with the data law firms in San Francisco already have?
Yes, machine learning models can work with the data San Francisco law firms already have, such as contracts, case files, billing records and email. Models can classify documents, extract clauses and find similar past matters. The data can stay in your own environment with access controls and audit logs, and an NDA comes first. AI search over documents starts from $2,500. See our legal software work.
Build vs Buy Cybersecurity Software: How to Decide in 2026
Web development
Every security leader faces the same question at some point: should your organization build its own cybersecurity tools or buy software from a vendor? The stakes are high, and the wrong call can drain budgets, slow down your security team, or leave dangerous gaps in your defenses. This guide walks through the real tradeoffs, costs, and decision criteria for U.S. and Canadian organizations weighing the build vs buy cybersecurity software question in 2026.
How to Build an AdTech Platform in 2026: A Practical Architecture & Development Guide
Data Science
Virtual Classroom Software Development Cost: Complete 2026 Guide
EdTech