Let's build together.
Talk with a senior engineer about your product idea, architecture, and what it would take to build it.
90+
Active Client Partnerships
80+ Person
Product & Engineering Team
100%
Your Code & IP Ownership
U.S.-Led
Delivery & Accountability
Services we offer
- 01Data Science Services
> SMART MODELS, REAL DECISIONS <
Our data science services cover predictive analytics, forecasting, optimization, segmentation, and recommendation engines. Every data scientist on our team examines your existing systems, databases, reports, and operational tools to discover where machine learning models add measurable value first. Data science techniques improve predictive analytics in AI, which is why we focus on interpretable outputs that Scranton leadership can trust and act on. We handle model training, validation, and deployment so your team receives production ready results instead of notebooks that never leave a laptop. Machine learning relies on data engineering for model training, and we treat that foundation as seriously as the algorithms themselves. Many Scranton, PA, companies still rely on manual spreadsheet analysis, inconsistent metrics, and slow experiment cycles. Our senior data analyst and data engineer teams design pipelines that turn raw operational data into actionable insights your managers can use every morning. Predictive models are used to detect fraud and mitigate risks in regional industries, while forecasting models help operations teams anticipate demand shifts weeks ahead. We work with Python, SQL, scikit learn, and proven ML frameworks, choosing tools that match your actual data volume rather than overengineering. Data science enhances AI by analyzing large datasets, and we apply that principle with discipline so every model earns its place in your workflow.
- Forecasting that matches real demand
- Clear model monitoring and retraining schedules
- Fewer manual estimates across departments
- Segmentation aligned to actual customer behavior
- Interpretable outputs for leadership review
> PRODUCTION GRADE, NOT PROOF OF CONCEPT <
What separates a useful model from a forgotten experiment? Our data engineers ensure every model ships with automated testing, version control, and continuous monitoring so it stays accurate after launch.
- Automated retraining pipelines
- Version controlled model artifacts
- Alerting on prediction drift
- Documentation for internal teams
- 02Data Analytics Solutions
> FROM SPREADSHEETS TO CLARITY <
Our data analytics solutions cover dashboards, self service reporting, KPI design, metric definitions, and visual analysis layers. Companies use data analytics to enhance decision making efficiency, and that starts with eliminating the confusion that happens when different teams report different numbers. We audit your current reports, identify duplicated logic and inconsistent formulas, then consolidate everything into a single reporting model. Business analytics combines data, technology, and business strategy, so our work connects those three elements instead of treating analytics as a separate initiative. Scranton companies benefit from tailored analytics programs that match their actual operational rhythm. Slow reporting cycles and numbers that nobody trusts are problems we encounter in almost every engagement. Our team sets up dashboards for leadership, managers, and operators with only the signals they actually use. Business analytics transforms raw data into actionable insights, and we make sure those insights reach the right person at the right moment. Automated dashboards can replace manual spreadsheets for tracking operational metrics, freeing your staff to focus on decisions rather than data entry. Every visualization we design answers a specific question, so your business intelligence layer earns attention instead of collecting dust.
- Single source of metrics across departments
- Fast ad hoc questions without IT tickets
- Visuals that non technical teams understand
- Scheduled reports delivered on your own schedule
- Consistent KPIs from meeting to meeting
- 03Enterprise Data Management
> ONE DATA FOUNDATION <
Our enterprise data management services cover data warehouses, data lakes, integration pipelines, master data, and documentation. Data engineering ensures data quality for AI applications, and that same discipline applies to every operational reporting need your company has. We start with discovery and mapping of all existing systems, databases, spreadsheets, and files to understand what you actually have. Custom solutions can integrate with existing systems for seamless operations, and our engineers design schemas and pipelines that connect those tools without forcing disruptive replacements. Data science can consolidate information from various sources into automated reports and dashboards, but only when the underlying foundation is reliable. The messy reality we find in most Scranton organizations includes data scattered across tools, exports saved on local machines, no clear ownership of tables, and repeated manual merges every week. We standardize formats, deduplicate records, and establish naming conventions plus documentation so new team members can understand the system on day one. AI systems require structured data from engineering processes, and our pipelines ensure that structure is maintained automatically. Digital transformation streamlines operations through process redesign, and a solid foundation for data is where that redesign begins. Data driven environments emerge from coherent digital transformation plans, not from isolated tool purchases.
- Central warehouse architecture
- Automated ingestion jobs from all data sources
- Versioned transformations with clear lineage
- Data catalog summaries for every table
- Reduced manual merges and exports
- 04Data Strategy and Governance
> DATA THAT PEOPLE TRUST <
Our data strategy and governance work creates a concrete plan that ties every analytics effort to your actual business priorities. Data driven decision making relies on statistical modeling to allocate resources effectively, but that only works when definitions are consistent and access rules are clear. We run workshops where we map decisions to data sources, identify critical metrics, and get aligning stakeholders around shared naming and logic. IT consulting addresses fragmented tools and unclear data flows, and governance is how you prevent that fragmentation from returning after cleanup. Consultants design future state architecture with realistic roadmaps, and our strategy work follows the same principle of practical phasing. Governance is not a bureaucratic exercise. It means access controls, data quality standards, ownership, and policies for changing definitions so teams share data without confusion or compliance worries. We define roles and processes so changes to metrics or tables happen in a controlled way, with documented rationale. Advanced analytics can improve decision making by identifying operational inefficiencies, but only when the underlying data is governed well enough to be trusted. SoftDoes connects leadership, legal, and technical staff to agree on how data is collected, stored, and used. Digital transformation reduces manual workflows and bottlenecks, and clear governance removes the confusion that creates those bottlenecks in the first place.
- Clear ownership per dataset
- Access by role not by request email
- Change logs for core metrics
- Documented policies for definition updates
- Alignment between technical and business teams
> SMART MODELS, REAL DECISIONS <
Our data science services cover predictive analytics, forecasting, optimization, segmentation, and recommendation engines. Every data scientist on our team examines your existing systems, databases, reports, and operational tools to discover where machine learning models add measurable value first. Data science techniques improve predictive analytics in AI, which is why we focus on interpretable outputs that Scranton leadership can trust and act on. We handle model training, validation, and deployment so your team receives production ready results instead of notebooks that never leave a laptop. Machine learning relies on data engineering for model training, and we treat that foundation as seriously as the algorithms themselves. Many Scranton, PA, companies still rely on manual spreadsheet analysis, inconsistent metrics, and slow experiment cycles. Our senior data analyst and data engineer teams design pipelines that turn raw operational data into actionable insights your managers can use every morning. Predictive models are used to detect fraud and mitigate risks in regional industries, while forecasting models help operations teams anticipate demand shifts weeks ahead. We work with Python, SQL, scikit learn, and proven ML frameworks, choosing tools that match your actual data volume rather than overengineering. Data science enhances AI by analyzing large datasets, and we apply that principle with discipline so every model earns its place in your workflow.
- Forecasting that matches real demand
- Clear model monitoring and retraining schedules
- Fewer manual estimates across departments
- Segmentation aligned to actual customer behavior
- Interpretable outputs for leadership review
> PRODUCTION GRADE, NOT PROOF OF CONCEPT <
What separates a useful model from a forgotten experiment? Our data engineers ensure every model ships with automated testing, version control, and continuous monitoring so it stays accurate after launch.
- Automated retraining pipelines
- Version controlled model artifacts
- Alerting on prediction drift
- Documentation for internal teams
PRODUCTS BUILT ACROSS INDUSTRIES
Finance
We design data analytics solutions for reconciled reporting layers, audit friendly data trails, and secure field access. Our work helps reduce manual spreadsheet effort during closing and periodic reviews.
Healthcare
Integrating clinical and operational data with strict access controls and quality checks is core to our enterprise data management work. We handle deidentification, role aware views, and careful pipeline monitoring.
Education
Our data science services unify admissions, learning platform, and financial aid data. We forecast enrollment, track student outcomes, and design dashboards that leadership teams use for resource planning.
Construction
Project schedules, cost information, and field reports feed into a central data analytics solutions layer. We track progress, surface risk signals from historical data, and connect office and site systems together.
Technology
Product usage analytics, experiment reporting, and subscription metrics are part of our Scranton data science services. We organize event data into models that product management and marketing teams can act on.
Startups
Lean analytics setups with clear data strategy and governance help founders track core KPIs without overengineering. We set up minimal but solid tracking that extends as the company matures.
Compliance
Strict audit trails and access logging require disciplined enterprise data management. We design data lineage, change histories, and documented transformations, coordinating with internal legal and compliance teams.
Energy
Time series analytics, asset data, and operational dashboards are central to our data analytics solutions for this sector. We forecast usage and performance, and detect anomalies on sensor streams.


Transparency at each stage
Discovery & Alignment
Defined goals and a precise roadmap ensure your vision is realized without unexpected pivots or hidden costs.
Technical Strategy
Senior engineers select the optimal tech stack with clear architectural reasoning for long-term scalability.
Iterative Development
Gain real-time access to code and staging environments with regular demos to track every milestone as it happens.
Careful Testing
Receive transparent QA, security, and performance audits to ensure a flawless and stable launch every time.
Deployment & Support
Stay in total control with full documentation and proactive monitoring to keep your systems running at peak performance.
Numbers Don’t Lie
Recent projects showcasing how we design, engineer, and deliver production-ready software solutions.

- Startup
- Real Estate
Our Haus AI
A finance professional turned founder built Our Haus AI, an AI-powered collaborative workspace where homeowners and contractors scope, bid, contract, and document renovation projects together. SoftDoes took her prototype and made it production-ready.- 10XMVP scope delivered
- 2+years Ongoing partnership
- 1Fully owned Platform

- Finance
- Energy
Deepwater Insights
Deepwater Insights delivers proprietary alternative data and niche research on the offshore drilling and energy sector to institutional investors, family offices, and high-net-worth individuals who require coverage that larger firms don't provide.- 100%Brand Continuity
- 2Platform Distribution
- 100%Paywall-Ready Content

- Real Estate
The building buyer
The Building Buyer is a Florida-based real estate investment firm co-founded by Dylan Troiano and Charles Hanlin. They acquire single-family, multifamily, and commercial properties across South Florida and beyond, with a focus on motivated seller opportunities.- 18Weekly hours saved
- 2+Years Ongoing partnership
- 1Fully owned Platform

- Education
- Non-Profit
WOVEN & NICE
Woven is a Spring Valley, NY nonprofit running the NICE program (New Training Inclusive Community Environment) in four Rockland County schools. Their team supports students through restorative practices, mediation, and professional development for teachers and administrators.- 4Schools Served
- 4Weeks to Launch
- 1STTime on Upwork

- Healthcare
CareInTouch
CareInTouch is a Bay Area home health agency providing skilled nursing and therapy services to patients referred from hospitals and clinics. With over 100 staff, they operate in one of the most complex and compliance-driven healthcare markets in the country.- 40% Reduction In Billing Errors
- 100+Staff Operations Managed
- 0Missed Compliance Deadlines

- Startup
Sparkle The Cleaning Service
Sparkle The Cleaning Service is a Detroit-area residential cleaning company with 10 years in business, connecting homeowners with vetted, insured independent cleaners through a subscription-based marketplace platform.- 75% Platform Transparency
- 2XPlatform Growth
- 40%Higher User Retention

- Startup
DineMate
DineMate is a Maryland-based dating and connecting platform built around verified profiles, restaurant reservations, and prepaid dining experiences. Founded to bring back authenticity to how people meet and connect.- 60% Time Saved
- 99%System Reliability
- 40%Higher User Retention

- Healthcare
Prior Authorization AI
Prior Authorization AI is a healthcare automation startup building AI-powered tools to streamline prior authorization for Medicare and Medicaid medical transportation providers in New Jersey.- 16Weekly hours saved
- 63%Admin time reduced
- 43%Fewer submission errors

- Education
Grand Central Language Services
Grand Central Language Services provides translation and interpretation for organizations operating in complex, multilingual environments. As demand grew, internal workflows became harder to manage. SoftDoes built a custom platform to streamline coordination, improve visibility, and support scalable operations.- 72%Workflow Reduction
- 48%Coordination Reduction
- 83%Visibility Increase

- Healthcare
FMY Orthodontics
FMY Orthodontics, a multi-location practice in West Tennessee, partnered with SoftDoes to replace a spreadsheet-based financial workflow with a custom web platform. The goal was to simplify how staff present treatment financing while allowing patients and families to review and complete decisions remotely.- 60%Workflow Reduction
- 75%Remote Adoption
- 5Locations Aligned

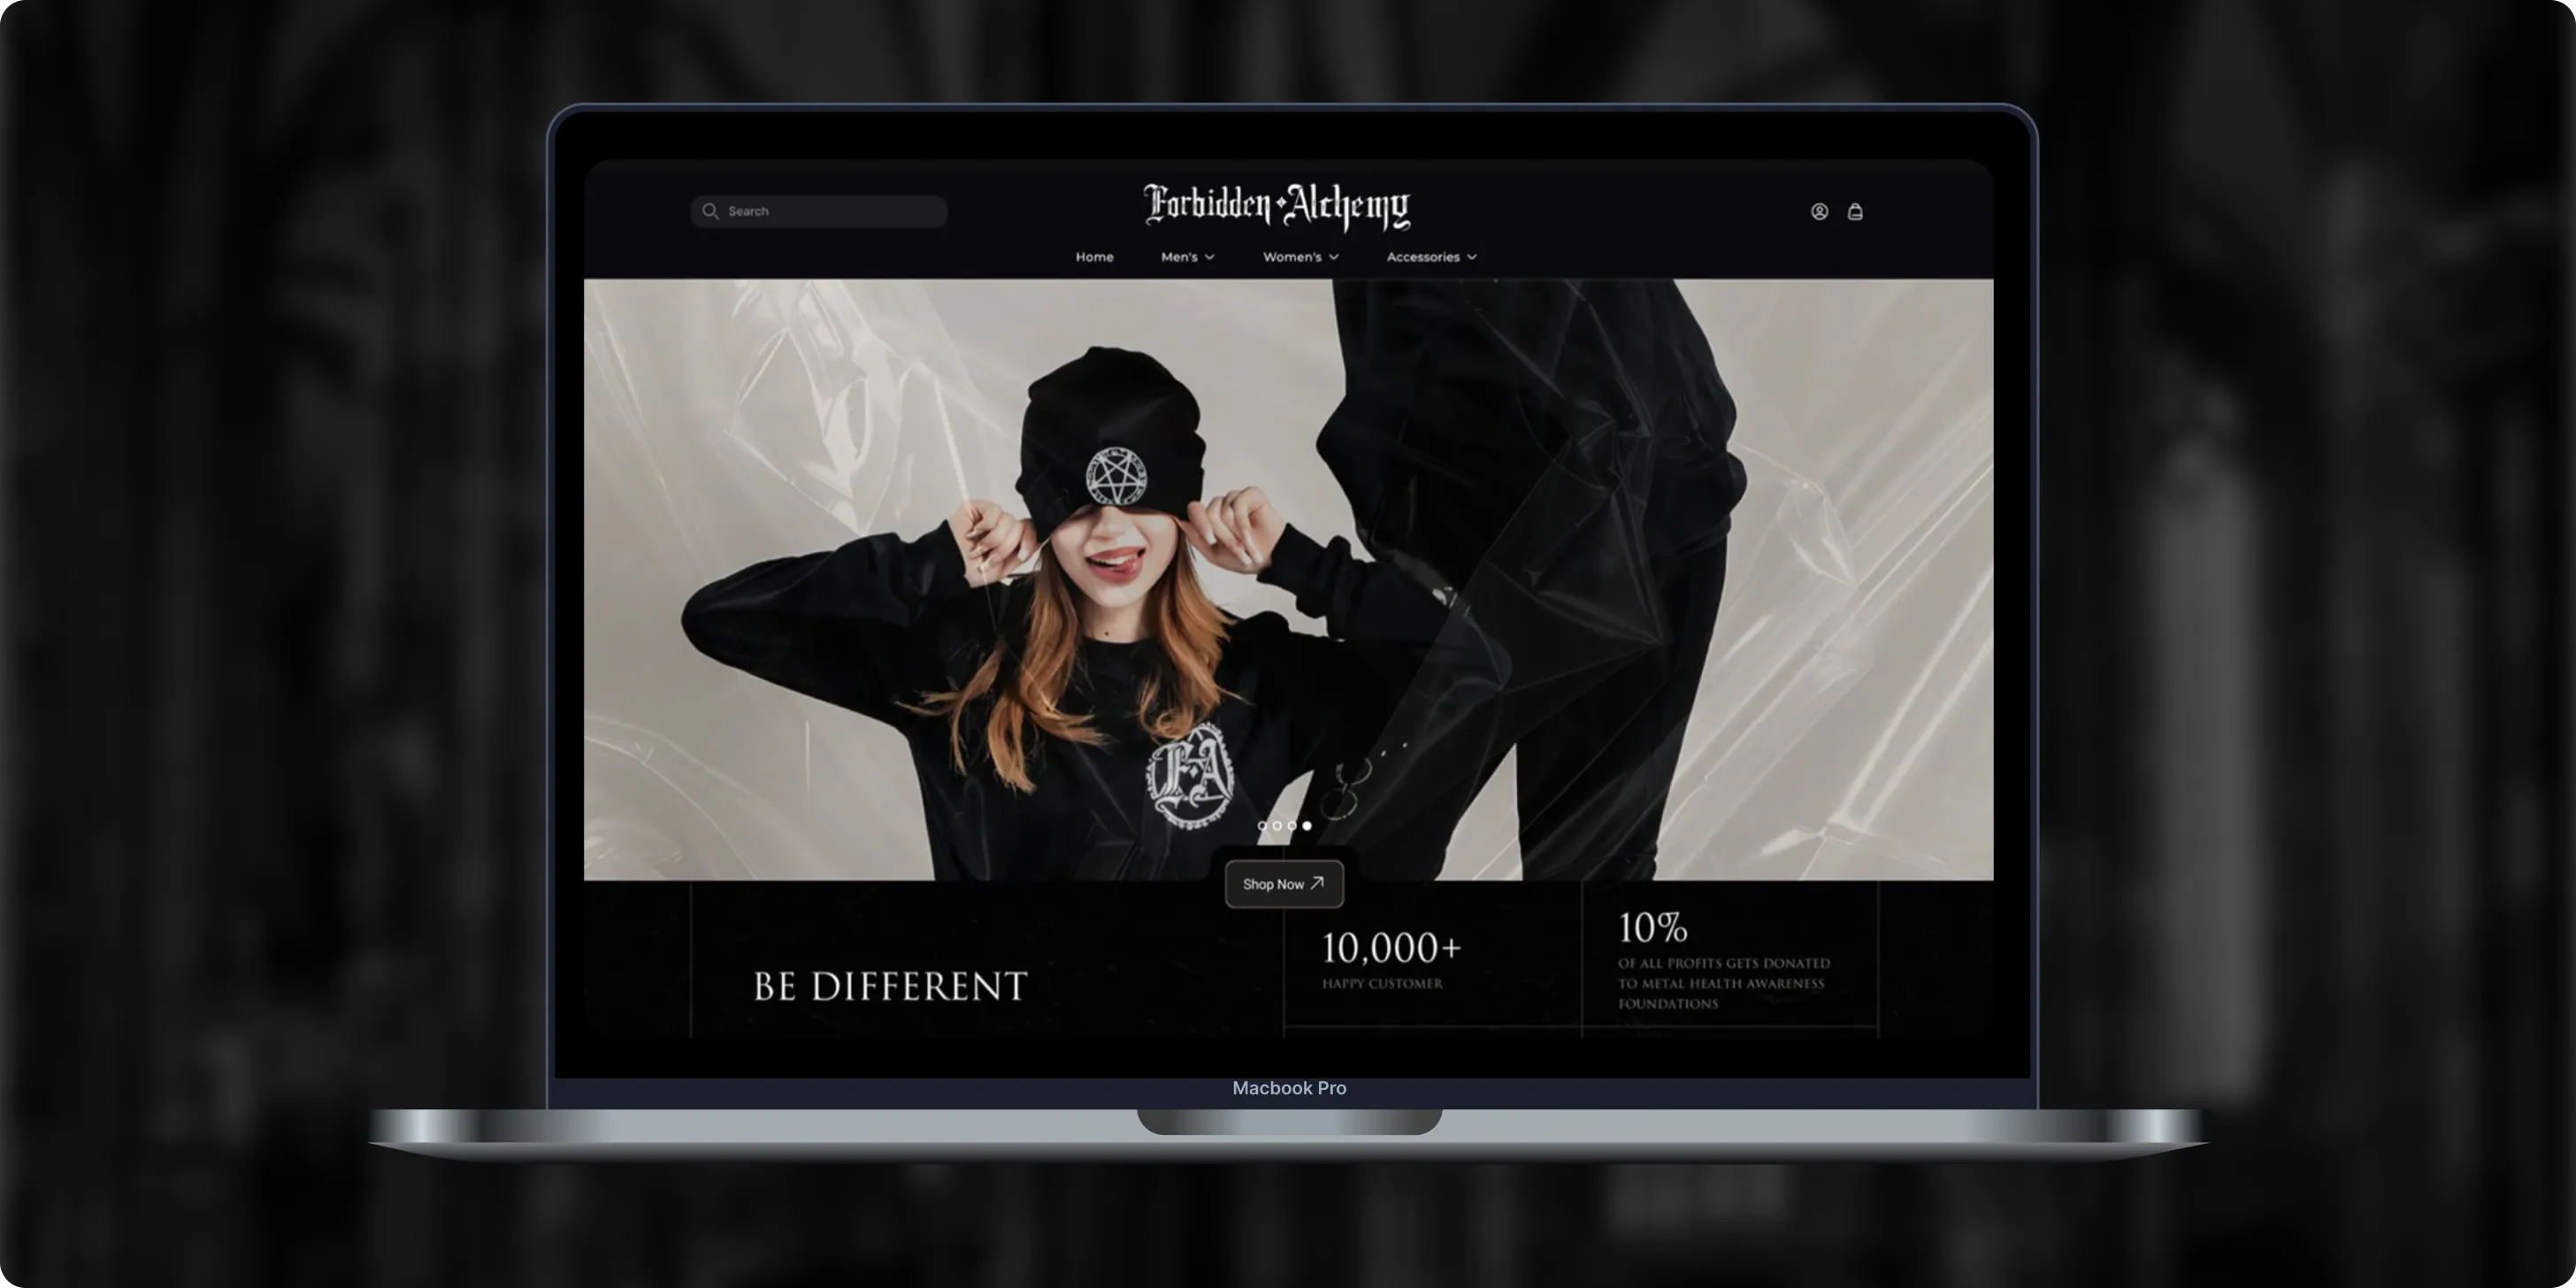
Forbidden Alchemy
Forbidden Alchemy is an alternative fashion brand creating dark, provocative clothing for the metalhead community, with 10% of profits donated to mental health awareness. Its mostly mobile audience struggled with a store that was hard to navigate and weak on functionality.- +44%Revenue Month Over Month
- 86%Design Satisfaction
- 2.8XUser Retention Growth
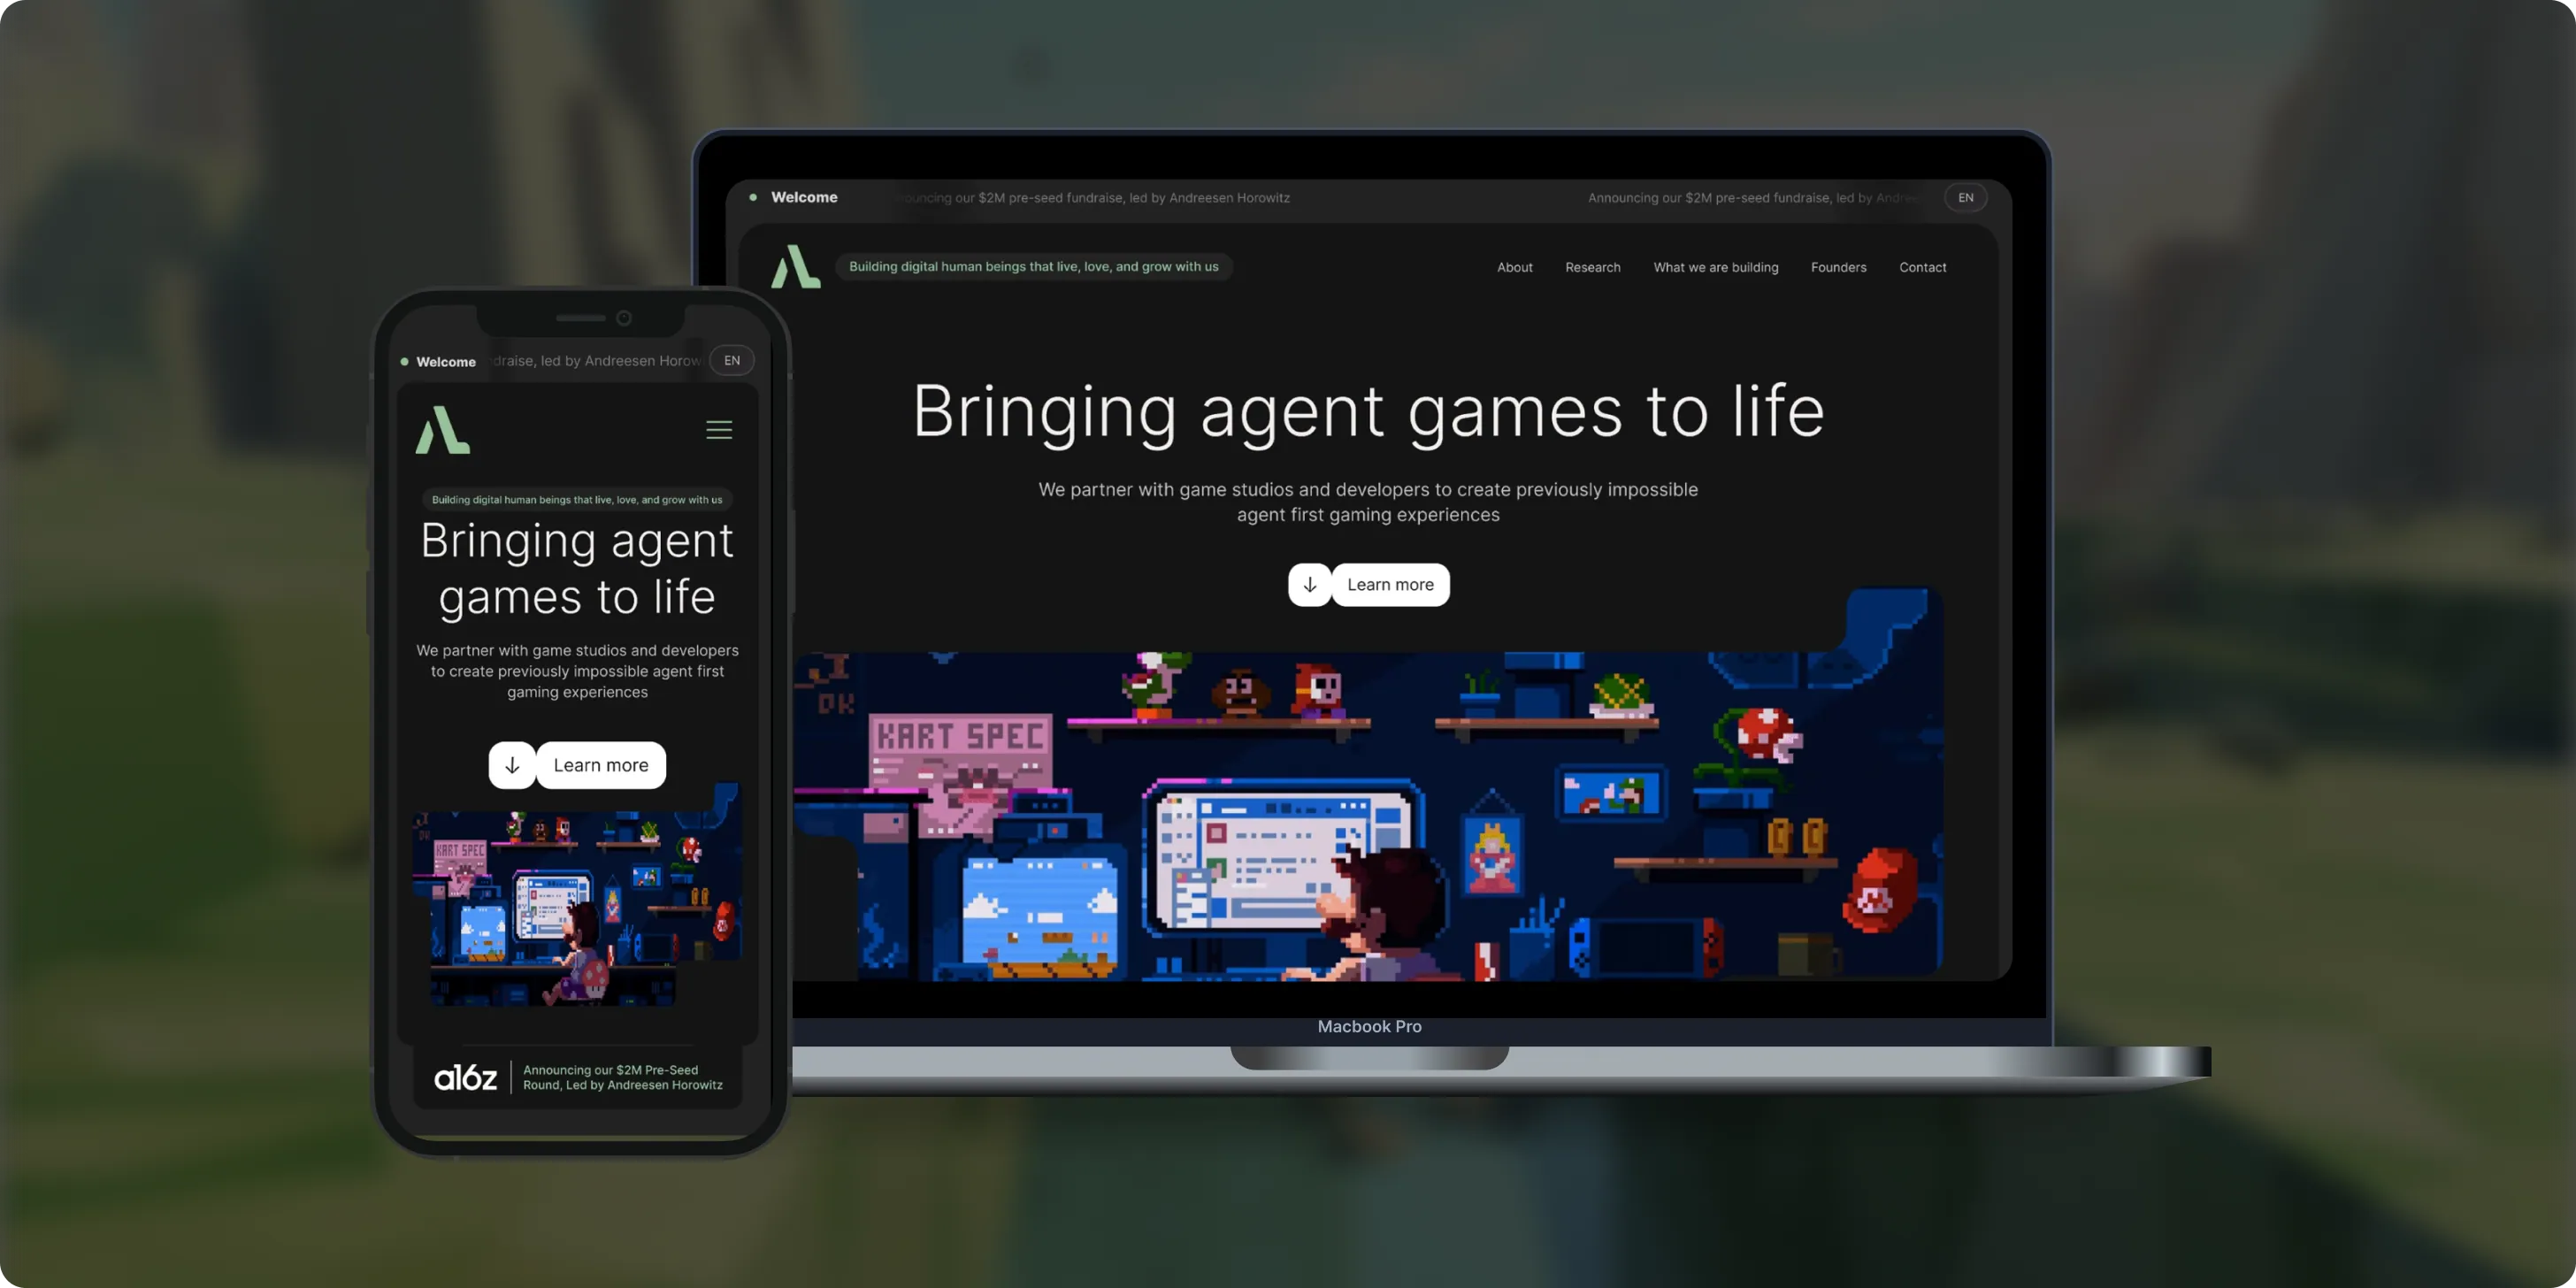
Altera
Altera builds on decades of computational neuroscience research to create digital human beings for gaming. Backed by a $2M pre-seed round led by Andreessen Horowitz, the team needed a landing page that could explain complex agent technology to players, partners, and investors.- 98%Dynamic Customization
- 100%Streamlined Navigation
- $2MPre-Seed Round
- Real Estate
Brizacorp
Brizacorp manages residential properties and coordinates the staff who handle painting, cleaning, and repair requests. Its team tracked work across messengers, phone calls, e-mail, and paper planners, with no single place to manage requests or measure performance.- 98%Application Stability
- 95%Utilization Rate
- 30%Faster Task Completion
Color & Harmony
Color & Harmony is a Kentucky-based color consulting studio led by certified color strategist Diana Cartaya. The studio needed a website that reflects its refined aesthetic, showcases its portfolio, and explains a science-based color process in simple language.- 45%Conversion Rate Increase
- 50%Higher User Engagement
- 2Months to Launch
The Modern Gentlemen
The Modern Gentlemen sells premium men's skincare featured in Men's Health, GQ, and Men's Journal. Its customers wanted an efficient routine, but generic product suggestions and limited skincare knowledge made choosing the right products hard.- 30%Increase in Conversions
- 25%Higher Customer Retention
- 92%Mobile Purchases
OQ Technology
OQ Technology connects IoT devices, machines, and people anywhere on the planet through its satellite network, serving energy, maritime, logistics, agriculture, and mobile operators. Its website made it hard to explore products and reach pricing plans.- 4Pricing Plans Clarified
- 3Dedicated User Flows
- 1Unified Platform
- Real Estate
- Finance
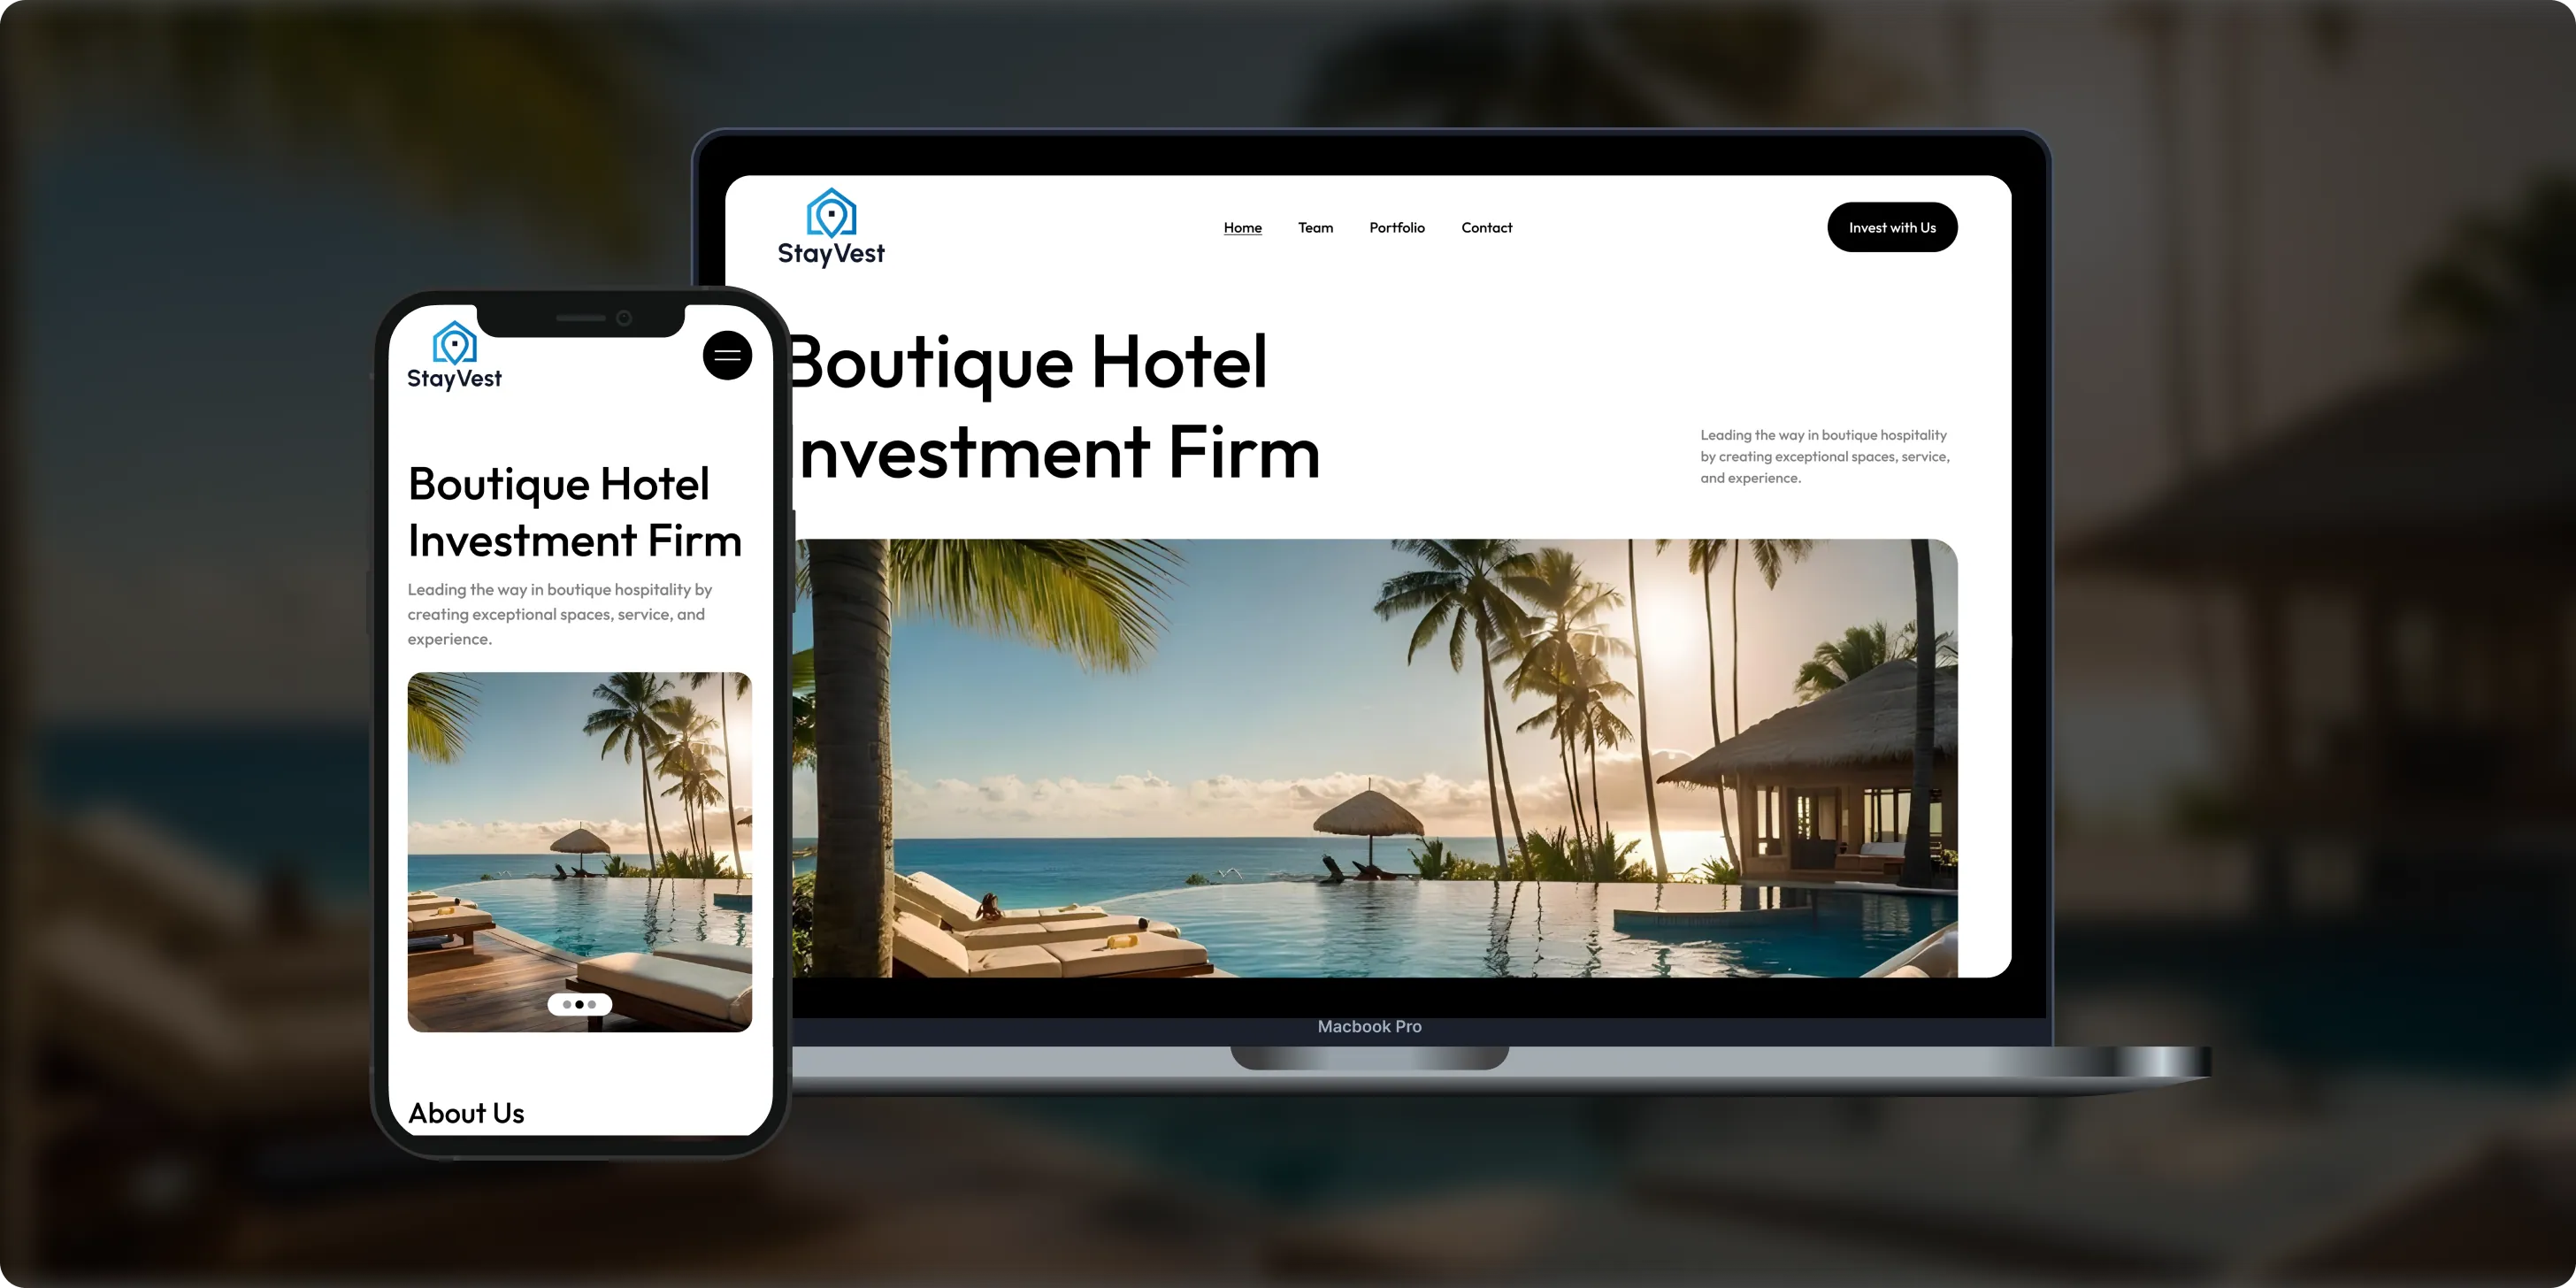
Stay Vest
Stay Vest is a private real estate investment firm that acquires, renovates, and operates boutique hotels for cash flow, tax benefits, and equity gain. It needed a platform that explains its strategy and earns the trust of passive investors.- 1,500+Guest Stays
- 200+Rooms Managed
- 5States Covered
Bokeyno Motorsports
Bokeyno Motorsports is the leading mobile installer of vertical doors for high-performance cars. This Shopify website isn’t just about services—it’s a bold statement of power, style, and expertise. With a sharp layout, strong visuals, and real-world case studies, the site delivers all the information car enthusiasts need to book confidently and instantly.- 54%Booking Requests
- 43%Lead Conversion
- 32%Qualified Inquiries

ai document processing platform
A comprehensive talent solution designed to help companies attract, hire, and retain top talent more effectively. The platform combines AI-powered recruitment technology with employee financial wellbeing programs, enabling smarter hiring decisions while supporting employees’ financial stability and long-term engagement.- 62%Faster Processing Time
- 78%Less Manual Work
- 35%Improved Accuracy

WHAT CLIENTS SAY
Independently verified reviews from real clients on Clutch.co


Client Story
Real feedback from
FMY Orthodontics
“Their perseverance and solution-oriented mindset. SoftDoes consistently found ways to make things work, added features we had not originally envisioned, and never became frustrated. It felt like working with a true partner who cared about the success of our practice.”
Dan Merwin
DDS, MS -- President, FMY Orthodontics

Client Story
Real feedback from
Prior Authorization AI
“Every time I sent a request, if there was anything that didn't work, they were able to turn it around quickly. Even when there were no updates yet, they always reached out to let me know they were working on it.”
Joseph Oluwo
Founder of Prior Authorization AI


Client Story
Real feedback from
WOVEN
“What stood out most was their commitment to understanding our needs before presenting solutions.”
Danna Pastran
Administrative Operations Manager, WOVEN

Client Story
Real feedback from
Grand Central Language Services
“The site performs as intended and provides the foundation for our company's digital presence.”
Joe Goldstein
QA Manager, Grand Central Language Services


Client Story
Real feedback from
DineMate
“They go above and beyond.”
Eric Snead
CEO, DineMate "Dating Connecting Platform"
WHAT CHANGED IN PRACTICE
Clients didn’t stay because of promises. They stayed because delivery became predictable, ownership was clear, and the product kept moving forward after launch.
- 01Direct Access to Senior Engineers
Every engagement at SoftDoes is led by senior engineers who design models, warehouses, and pipelines themselves. You speak directly with the people writing code and making architecture decisions. There are no layers of account managers or project coordinators filtering your questions. This means faster real time feedback on technical tradeoffs, fewer misunderstandings, and better alignment with your actual business outcomes. Juniors may assist with well defined tasks, but seniors own every critical decision. That structure is especially important for complex data science work where nuance determines whether a model actually performs in production.
- 02Predictable Delivery
We manage work in small milestones with clear acceptance criteria so progress is visible every week. Check ins happen on a regular cadence, and status reports include what was completed, what is next, and any risks we see. Even shorter analytics projects receive this structure because predictability matters regardless of scope. Estimates include honest technical uncertainty, and we explain tradeoffs when scope shifts rather than absorbing confusion silently. Our data analytics solutions engagements follow the same rhythm as larger platform programs. Demo sessions, change logs, and written summaries replace guesswork at every step.
- 03Built to Last Past Launch
We design models and pipelines for maintenance, extension, and clear ownership from the first week of work. Code quality, tests, continuous monitoring, and documentation are standard parts of every delivery. Our enterprise data management and data science services always include handover planning as a core activity, not an afterthought. Scranton teams can choose to maintain systems themselves or keep SoftDoes involved for continuous improvement. Schema design and metric definitions are structured so future analytics work does not conflict with what already exists. We treat your system as something that must run reliably long after our engagement ends.
- 04No Babysitting Required
Our engineers investigate issues, propose options, and choose sensible defaults when decisions are small enough to not require executive input. This frees local teams in Scranton to focus on their actual responsibilities instead of micromanaging external resources. We proactively clarify questions around data strategy and governance so ambiguity does not slow down delivery. Every assumption and decision is documented so clients have a clear trail they can review anytime. When we see recurring issues or identify automation opportunities, we suggest improvements rather than waiting to be asked. The result is a partnership where your team gains capacity instead of adding management overhead.
Technologies We Use
DATA ANALYTICS & BI
DATA SCIENCE & ML TOOLS


DATA PLATFORMS & WAREHOUSES


BIG DATA & DATA PROCESSING


























Frequently Asked Questions
Everything you need to know about working with SoftDoes. Can’t find an answer?
How is communication handled for data science services engagements?
Communication happens through video calls, messaging tools like Slack or Teams, and shared project documents. We match our meeting rhythm to Scranton office hours and adjust frequency based on how active the current milestone is. After every key call we send a written summary with decisions, open questions, and next steps so nothing gets lost. You always know who your lead engineer is and how to reach them directly. Our approach ensures essential information flows without unnecessary overhead or delays. We adapt the cadence as the project evolves, adding or reducing touchpoints based on what actually helps.
What types of data projects are a good fit for SoftDoes?
We work on analytics platform modernization, dashboard programs, forecasting models, warehouse design, and data pipeline engineering. Both focused short efforts and longer data platform initiatives fit our model well. Complexity and the need for thoughtful engineering matter more than size alone. Our data analytics solutions engagements range from quick diagnostic audits to multiphase platform programs. We are comfortable joining existing internal teams as embedded specialists or acting as the primary data group for companies without one. Every project receives the same senior attention and structured delivery process.
How do you handle data privacy and security during model training?
We separate development, staging, and production environments and apply least privilege access controls throughout. Sensitive data is anonymized or masked before model training wherever possible to minimize exposure. Our enterprise data management design includes logging and access tracking so every interaction with data is recorded. We review data sharing requirements with the client and avoid copying data where it is not needed. Security steps are documented and reviewed with your IT or security contacts before work begins. Compliance with regulatory frameworks is critical for data management in sectors like healthcare and finance, and we respect those requirements fully.
How do you handle scope and changes in data science projects?
When new requests arrive we write an impact note outlining options, tradeoffs, and effects on timing. Minor adjustments inside a milestone are often absorbed with clear acknowledgment and an updated task list. Larger changes go through explicit confirmation from the client before any work starts. Our approach to data strategy and governance means that scope changes are evaluated against the overall project goals, not just the immediate request. Nothing shifts without your agreement, and we keep a written record of every decision. This process reduces surprises and keeps both teams aligned throughout the engagement.
What happens after launch of a data science solution?
After launch we enter a focused period where we watch logs, metrics, and user feedback to catch early issues before they affect operations. We conduct training sessions for your internal teams so they can operate dashboards, pipelines, or machine learning models independently. Some clients keep SoftDoes involved for ongoing roadmap work and continuous improvement. Others transition fully in house using the documentation and recorded walkthroughs we prepare. Our data analytics solutions come with runbooks and monitoring guides so your team has everything needed to operate confidently. Handover is planned from the first week, not treated as an afterthought.
Will we own the code and IP from data science work?
Yes. You own all project specific code, data models, and documentation as defined in the contract. Generic internal accelerators or templates we use remain with SoftDoes, but they are never required to run your system. Your data always stays under your control regardless of the engagement status. This ownership structure allows Scranton organizations to continue work with or without us at any point. We design for independence because it is the right thing to do for long term client relationships. The goal is that your company walks away with a complete, self sufficient system.
What makes SoftDoes different from a typical agency providing data science services in Scranton?
We involve senior engineers directly in every conversation, from initial data analysis through deployment. Our Scranton data science services go deeper than surface level dashboards or one time reports. We tie every feature or dataset to a specific decision or business question rather than checking off a list of tools. We are comfortable working with legacy systems, messy data, and complex integrations that other firms may avoid. Maintainability matters more to us than quick demos that look impressive but break within weeks. Our calm, structured process and focus on data fundamentals is what sets us apart from consulting services that prioritize speed over substance.
How do you price projects that involve data science services?
We typically work with project based pricing or structured retainers depending on the engagement type. Scope, complexity, and the level of technical uncertainty influence every proposal we prepare. For some clients we start with a smaller discovery or audit focused on data analytics solutions before committing to a larger program. All pricing is discussed openly and adjusted only with client agreement through documented change processes. Detailed statements of work reduce surprise on both sides and set clear expectations. We keep our approach transparent so Scranton data science services clients always understand what they are paying for and why.
EHR Software Development Cost in 2026: Complete Budgeting Guide for U.S. & Canadian Healthcare
Healthcare
Building a custom electronic health record system is a major technology investment for healthcare organizations. However, the cost discussion is often unclear due to varying vendor quotes, underestimated compliance layers, and confusion between EHR, EMR, and practice management software.
How to Build an E-Learning Platform in 2026: Strategy, Architecture, and Costs
EdTech
The global eLearning market surpassed $325 billion and continues to grow as enterprises, universities, and independent creators invest in digital education across the U.S. and Canada. If you are planning to build an e learning platform, the decisions you make in the first few weeks will shape your costs, timeline, and competitive position for years. This guide covers everything from choosing a business model to launching an MVP, written from SoftDoes' perspective as a software engineering partner for regulated, high demand industries.
Legal Case Management Software Development: A Complete Guide for Law Firms in 2026
Web development
Legal case management software is the operational backbone of modern law firms. It coordinates every moving piece of a practice, from matter intake and deadline tracking to billing, document automation, and client communication, all within a single system. The legal case management software market was valued at $8.7 billion in 2023, is growing at a CAGR of 11.5% from 2024 to 2031, and is forecasted to reach $12.3 billion by 2031. With 88% of lawyers now using cloud computing software for case management, firms across the U.S. and Canada are moving past generic tools and investing in custom platforms that reflect how they actually practice law. This guide covers how to plan, build, and evolve a custom legal case management system, not just how to pick a product off the shelf. SoftDoes is a U.S. and Canada focused software engineering partner with deep experience in LegalTech and regulated industries, and we'll reference their approach throughout.